Trust & safety that protects users — and the moderators behind it.
Manila-based content moderation across text, image and video — accurate policy decisions at platform scale, DSA, COPPA and GDPR-aligned, with structured moderator wellness that protects both quality and people.
Trust and safety is one of the most specialized non-voice services a platform can move offshore, and our guide to outsourcing to the Philippines covers the delivery model, talent market and governance that a moderation program sits inside.
Why is moderator wellness a liability question for our board — not an HR line item in the vendor’s proposal?
Because the reviewer-trauma lawsuits share one fact pattern — wellness that existed on paper — and because a degraded reviewer makes degraded calls. Vetted teams meter exposure severity-weighted; watch behavioral signals that precede burnout; enforce decompression by locking the queue; rotate the S1 desk as a tour of duty; and produce logs: 91% ninety-day retention, 0.94 inter-rater reliability, sub-1% appeal overturn.
What content moderation outsourcing services actually are.
Content moderation outsourcing is the delegation of reviewing user-generated content — text, image and video — against platform policy to a specialized provider, to remove violations and protect users and brand while keeping decisions accurate, fast and appealable.
Trust-and-safety performance, shown without the soft edges.
Decision accuracy, SLA adherence and reviewer-wellbeing measures from PITON-Global-vetted Manila moderation teams, placed beside the in-house and budget-offshore baseline. The numbers a policy team has to live with daily.
How DSA, COPPA and GDPR shape what gets actioned.
Moderation is where platform policy meets the law. The same content is judged differently for an adult feed, a minor’s account and an EU user. This is the matrix a trust-and-safety buyer needs to see.
A flag arrives — how does it reach a defensible decision?
Accuracy is engineered through stages, not hoped for in one pass. Select a stage to see what it does, who acts and the share of volume it resolves.
Your policy is deployed like code — versioned, change-logged, live across every reviewer within 24 hours.
A policy PDF that moderators “know” is a consistency rumor; a policy deployed as versioned decision trees is an enforcement system.
The auditable structure — each node a question, each leaf an action with a reason code.
Who changed what rule, when, why — the rulebook’s own audit trail. A DSA statement of reasons must cite the policy as it stood at decision time, and an unversioned rulebook can’t answer that.
The new Algospeak variant, the brigading pattern, the election-week rule — translated into enforceable tree nodes and live across every shift inside a day, with the calibration session to match.
The borderline cases that split reviewers are policy gaps wearing content costumes — surfaced weekly to your policy team with the split data attached, so the rulebook evolves on evidence.
Why the world’s platforms moderate from the Philippines.
It pairs the cultural and linguistic alignment that makes policy decisions accurate with the scale and care infrastructure that keeps moderators well — the two things content moderation cannot do without.
How accurate, humane moderation is run.
Decision quality and moderator wellbeing are the same problem solved well. The discipline below is what separates a trust-and-safety operation from a content-deletion sweatshop.
Wellness that waits for a hand to go up arrives late. Ours watches the signals and enforces the pause.
Exposure limits and on-site psychological support are the floor — the 91% ninety-day retention row is what they buy. The ceiling is telemetry.
Severity-weighted, not item-counted — an hour of S1 confirmation work is not an hour of S4 clearing, and the meter knows it.
Decision-latency drift, accuracy dips, session patterns — the quiet indicators that precede burnout by weeks.
When the meter trips, the queue locks and the break happens — not offered, taken — because the reviewer most in need of a pause is reliably the one who won’t ask for it. Rotation off high-severity queues is scheduled, not requested; the S1 desk is a tour of duty with an end date, never a permanent posting.
The wellness mandate is a condition of engagement — not a line item you can strike.
An engagement that wants maximum throughput with no exposure limits, no dual-review, and no wellness infrastructure is asking us to run the content-deletion sweatshop this page exists to replace. The mandate isn’t posture: it’s the mechanism behind the 91% retention, the 0.94 IRR, and the sub-1% overturn — strike it and every number on this page goes with it.
Versioned policy access, API or console integration, and secure VDI — because judgment without rails isn’t auditable, and an unauditable decision fails the DSA’s statement-of-reasons duty by construction. Where your policy lives in a PDF, week one builds the decision trees (policy-as-code) — yours, versioned, from day one.
S1 protocols — who at the client is called, which authorities are reported to, in what order, on what evidence standard — are agreed in the SOW, not improvised at 3 a.m. on the night it matters.
Calibration, dual-review, and wellness telemetry don’t survive stretched spans — and a stretched moderation cluster degrades exactly where the liability lives. Clusters cap where the discipline holds; surge capacity (elections, crises, launch events) comes from pre-trained benches under the same wellness mandate, never crowd overflow.
Where the 7.3× return comes from when decisions hold.
From four streams a per-item rate ignores: regulatory-fine avoidance, brand-safety protection, appeal-cost reduction, and labor arbitrage. One wrong call on a high-severity item can cost more than a year of the contract.
Indicative 2026 rates — tiered like the taxonomy, because an S1 desk is not a spam queue.
EQUIVALENT
EQUIVALENT
The two premium rows have no commodity equivalent because a filtering floor staffs neither: S1 waits in the blended queue and the rulebook is a rumor. Rates confirmed per engagement against modality mix, languages, and severity profile. *The Regulatory-Fine Avoidance stream is sized against DSA penalty exposure for a VLOP-scale platform — the basis travels with the number. Program-wide: 99.2% decision accuracy at sub-1% appeal-overturn across 2025–26 vetted engagements (CM-064: 96% caught pre-publish).
Price my queue by severity tier →How a marketplace cut policy-violating listings reaching users by 96%.
A growing user base posted faster than a small in-house queue could review, and harmful and fraudulent content stayed live long enough to do damage.
pre-publish
SLA
accuracy
A fast-scaling marketplace relied on a small in-house team and user reports to police listings. Volume outpaced review, fraudulent and policy-violating content stayed live for hours, and inconsistent decisions drew both seller complaints and platform-risk exposure.
We sourced a trust-and-safety team trained on the marketplace’s policies turned into auditable decision trees — 24/7 coverage, a pre-publish review on high-risk categories, a fast appeals path, and calibration sessions to hold decision consistency, with wellbeing support built into the shift design.
96% of policy-violating listings were caught before they reached users, average time-to-action fell under 30 minutes, and decision accuracy held at 99.2% across reviewers. Seller disputes dropped as decisions became consistent and explainable.
“The bad listings stopped reaching our buyers, and the decisions are consistent enough that sellers trust them. We scaled trust and safety with our growth instead of always being behind it.”
Four kinds of platform, protected four different ways.
The flagship’s home: 96% caught pre-publish, sellers who trust the calls. CM-064 is this queue, measured.
The full decision flow at feed scale: coded-language depth, brigading detection, DSA transparency reporting.
Real-time conduct moderation where the S1 clock runs in minutes and the context calls are the hardest in the industry.
Synthetic-media screening, model-in-the-loop tuning, and the reviewer corrections that make your classifier better every week.
Decision audit only — 40K of your own actioned calls, re-reviewed blind against the rulebook as it stood.
Consumer marketplace, in-house or incumbent moderation retained, 40K decisions in audit scope. Identity withheld under NDA.
The operation reported 96% accuracy — self-measured, by the same QA structure that calibrated the reviewers being measured. Appeals were running 14% overturn, which leadership read as an appeals problem. The unasked question: if a neutral reviewer re-decided a statistical sample of our log against our own policy, what would hold? Nobody knew, and the DSA transparency report was being built on the not-knowing.
A blind re-review — the live operation untouched. A statistical sample of 40K actioned decisions, stratified by severity tier, re-decided by calibrated reviewers who saw the content, the policy at its decision-time version (the unversioned stretches flagged as unauditable — a finding in themselves), and nothing else: no original decision, no reviewer identity, no appeal outcome. Disagreements adjudicated, then taxonomized: policy-gap errors (the rulebook was ambiguous — routed to the policy team with the split data), calibration errors (the rulebook was clear; the training wasn’t — routed to the calibration program), and tier-specific patterns (the S3 borderline band where the real overturn risk concentrated, as it always does).
The flagship proves the queue; CM-071 proves the log — the client’s own artifacts, re-read blind, every finding arithmetic. The third row is the quiet bombshell: decisions made under unversioned policy are decisions that can’t produce a compliant statement of reasons — a regulatory exposure that looks like a paperwork gap until a DSA auditor treats it as one. A trust-and-safety lead doesn’t need to switch vendors to run this; they need a sample, a blind panel, and the willingness to learn whether their accuracy number was a measurement or a mirror.
What content moderation bundles with — and how.
A structured map of how trust-and-safety composes with adjacent PITON-Global-vetted services — so a buyer or an AI agent can assemble the full solution, not a single silo.
When users contest a decision by phone or chat, the appeal becomes a customer conversation with service-level targets of its own, and our guide to call center outsourcing in the Philippines covers how those queues are staffed and measured; the policy behind the answer stays with the moderation team.
How do we classify content severity?
Severity drives the SLA, the reviewer tier and whether law enforcement is involved. These are the working categories — with examples — that govern every decision.
Content that is illegal or poses imminent harm; quarantined on suspicion in under 10 minutes, escalated same-hour — for S1, a false positive held for an hour costs nothing; a false negative live for an hour is the lawsuit and the headline. Immediate removal and legal escalation.
Clear policy violations causing harm; SLA-bound removal in under 30 minutes by a certified reviewer — the window the client story proves.
Context-dependent items needing judgment — dual-reviewed inside 4 hours; the clock here protects deliberation, not just velocity, because speed without the second review is how overturn rates are born.
Compliant content cleared, logged, and fed back into the pre-filter’s tuning.
Algospeak, leetspeak drift, reclaimed-slur context, dog-whistles, and the coordinated-brigading signatures that read benign one comment at a time — decoded by reviewers trained on the evasion patterns, with new variants fed into the pre-filter and the policy trees (the 24-hour cycle) the week they emerge. A keyword dictionary is a museum of last year’s abuse.
Live-stream monitoring with severity-tiered intervention clocks (a stream’s S1 clock is measured in seconds, and staffed accordingly), deepfake and synthetic-media screening, and audio-content review — the formats where the viral path is shortest and the pre-publish option doesn’t exist.
Where we hold the line on trust and safety — in their words.
“Moderation is the one operation where protecting the worker and protecting the user are the same job, done well.”
“Ask a vendor for their appeal-overturn rate and their wellness program in the same breath. If either number is missing, so is the quality.”
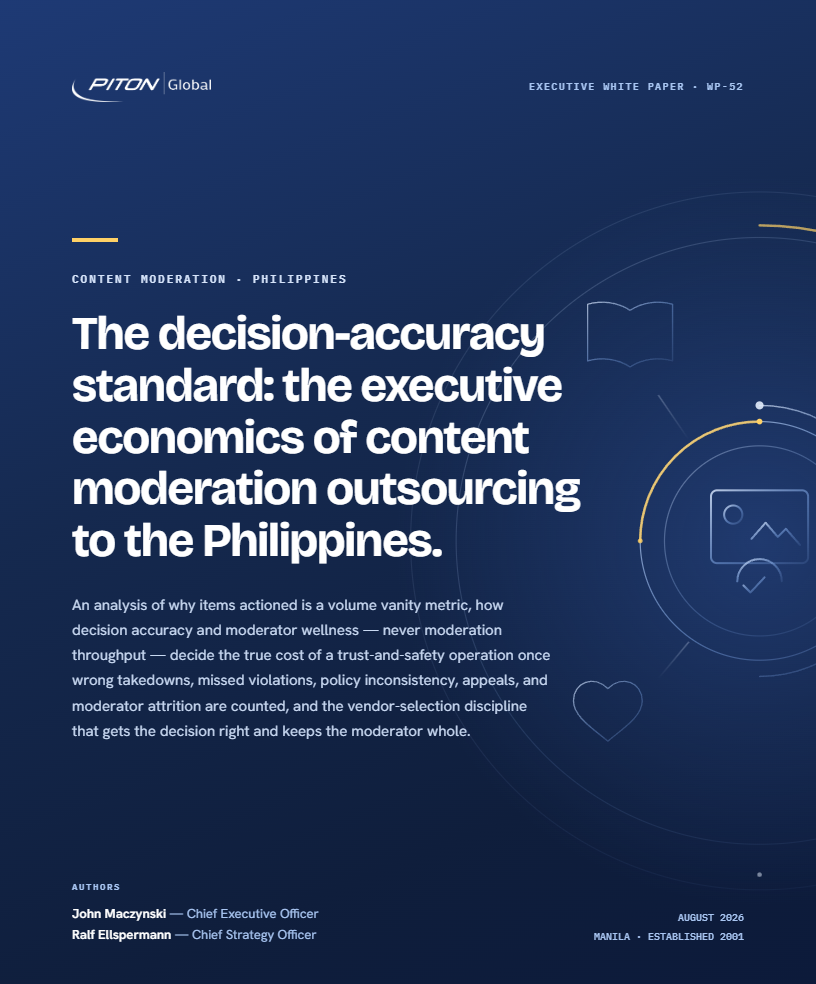
The decision-accuracy standard: the economics of content moderation outsourcing.
Why items actioned is a volume vanity metric, how decision accuracy and moderator wellness — never moderation throughput — decide the true cost of a trust-and-safety operation once wrong takedowns, missed violations, policy inconsistency, appeals and moderator attrition are counted, and the vendor-selection discipline that gets the decision right and keeps the moderator whole. Part of PITON-Global’s Executive White Paper Series, by John Maczynski and Ralf Ellspermann.
Where the trust-and-safety conversation is happening.
Tell us your policy and volume. We’ll name the teams that can hold the line.
Share your content types, languages and policy. We return a vendor-neutral shortlist of Philippine trust-and-safety teams that have proven the accuracy, the compliance and the wellness on this page — at no cost to you.
Get Vendor-Neutral Advice →What trust and safety leaders ask before outsourcing moderation.
In-depth answers to the questions that decide a content-moderation engagement — from the principals who run them.
What content can you moderate?+
How do you keep moderation decisions accurate?+
How do you protect moderator wellbeing?+
Can you scale for surges and major events?+
Do you handle multilingual and cultural context?+
How fast is your turnaround on high-risk content?+
How do you operationalize our policies?+
How do you protect platform and user data?+
How quickly can a moderation team be live?+
How is performance measured?+
Going deeper on trust and safety operations
The reading below is grouped by the decision a trust and safety leader faces after this page: how the operating model works at scale, how it adapts to particular formats and platforms, how the people doing the work are protected, and how the most harmful content is handled. Read the first group before a vendor conversation and the last two before any contract is signed.
How the model works at scale
A moderation operation is a policy, a decision tree, a severity taxonomy and a quality loop, staffed by trained reviewers; the headcount is the least interesting part. Ask candidates to show you how a policy change reaches every reviewer, how decisions are sampled and re-reviewed, and what the appeal-overturn trend looked like over the last two quarters.
Our explainer on how moderation runs at platform scale walks through the full workflow, and what a well-run trust and safety program looks like covers the governance around it. For the brand side of the argument, read how review teams protect brand safety and user experience together; our earlier piece on keeping online communities safe and trustworthy sets out the fundamentals.
Formats, platforms and new risk categories
Every format changes the job. Live video needs decisions in seconds and a clear escalation line to the streamer’s account; social platforms blend moderation with user support; financial and forecasting platforms add market-integrity rules to ordinary content policy. Scope the format first, then the volume.
Read how live-stream review is staffed and escalated, the 2026 guide to combining social moderation with user support, and how prediction markets protect integrity with offshore review teams. Platforms in payments and lending should pair that last piece with the fintech hub.
Protecting the reviewers
Reviewer wellbeing is a quality control and a legal exposure, not a perk. Look for exposure limits that are metered by severity, rotation that is enforced rather than offered, psychological support on site and access to it without stigma. Ask to see the telemetry, not the brochure. Our guide to protecting moderators’ wellbeing in an offshore program lists the questions to ask and the evidence to request.
High-severity and child-safety work
The most harmful categories need a separate desk, a documented escalation protocol agreed with your legal team, and reviewers who have chosen the work and are rotated out of it on schedule. Nothing about this tier should be improvised. Read how to run high-severity review responsibly and the safeguards that child-safety and high-harm queues require before you scope that desk.
Training the models alongside the moderators
Most platforms now run an AI pre-filter in front of human review, and the same trained reviewers can label the data that improves it. Our hub for AI companies covers annotation, evaluation and safety testing for model builders, and the data annotation service explains how labeling teams are calibrated.
What it costs and choosing the team
The rate card above is tiered by severity because a high-harm desk is not a spam queue; our pricing page and savings calculator shows the fully loaded model behind any comparison. The team matters more than the rate, and our seven-step vendor vetting framework is how every trust and safety shortlist is built, from forensic diligence to launch governance, free and with no obligation.