Move from lab to clinic without accumulating Research Debt.
Research documentation, clinical trial operations, genomics data processing and non-clinical back-office — by bioscience-literate Philippine specialists who pair Agentic Quality Checks with eTMF sovereignty to deliver 45% faster throughput and 99% eTMF completeness for biotech innovators and CROs.
BPO Suppliers
Programs Served
Service Delivery
In 2026, biotech success is defined by the speed at which a breakthrough moves from lab to clinic without accumulating Regulatory Debt. The Philippines has become a high-utility extension of the R&D lifecycle, where Agentic Quality Checks and eTMF sovereignty accelerate the path to market — 45% faster documentation throughput, 99% eTMF completeness.
Your science, your systems, and where Research Debt accrues fastest.
BT-071 was exactly this — Series B, two INDs, and a runway the eTMF gap was quietly consuming. Scalable trial administration, documentation and data operations that grow with the pipeline without building headcount ahead of your raise.
A 7.4% metadata error rate isn’t a data problem — it’s a contaminated $2.4M dataset and an IND-submission crisis. ACMG-aligned annotation, pipeline QC and sample-metadata governance at the <0.5% Scientific QC standard.
Same discipline, ISO 13485 rulebook. Technical documentation, complaint-handling operations and quality-system support for device and combination products under validated version control.
Your sponsors audit your files the way regulators audit theirs. eTMF management, site-document collection and Research Integrity Intelligence reporting your sponsor audits can consume directly.
What is Research Support Debt in biotech — and how does it silently delay breakthroughs from reaching patients?
It is the accumulation of fragmented lab documentation, incomplete eTMF artifacts, miscoded genomics metadata and unvalidated annotations that builds invisibly during discovery — then surfaces as an inspection liability or clinical-hold trigger at the submission window. Unlike software debt, it carries a direct human cost: every month of inspection delay is a month patients wait for a proven therapy.
Discovery Velocity is an operational architecture, not a research capability. It is the result of deploying a GxP-aligned Philippine partner to maintain continuous eTMF health, annotate genomics datasets with forensic accuracy, and operate a 21 CFR Part 11-validated documentation environment from day one of IND-enabling studies — so research support never becomes the bottleneck between discovery and development.
“The biotech organizations winning the discovery velocity race are not those with the most advanced research teams — they are those whose operational support infrastructure matches the ambition of their science. When discovery and documentation are synchronized from the start of IND-enabling studies, the lab-to-clinic timeline compresses. When they are not, the therapy that could have reached patients in 2027 reaches them in 2029.”
What does Agentic eTMF Sovereignty look like — and why is genomics data orchestration the most underestimated challenge in R&D?
Agentic eTMF Sovereignty is the model in which AI autonomously classifies incoming documents against the DIA TMF Reference Model, flags compliance gaps in real time and initiates query resolution — holding 99% completeness without manual filing. Genomics Data Orchestration is the Scientific QC layer that makes sequencing results defensible in submission.
“A sample metadata error that propagates through a WGS pipeline can invalidate an entire sequencing run. In a Phase I oncology trial, that is not a data quality issue — it is a patient safety issue and a regulatory submission crisis. Genomics orchestration sits at the intersection of scientific accuracy and regulatory compliance, and most BPO providers are equipped to handle neither simultaneously.”
The eTMF is the documentary foundation of every clinical program. An IND that cannot demonstrate 99% artifact completeness at filing creates reviewer delay that consumes runway. The Agentic eTMF architecture monitors completeness continuously, auto-classifies incoming documents within one hour, and flags gaps before they become inspection findings.
Genomics annotation requires a compound capability generic BPO talent pools do not contain: biological science literacy to understand the data, bioinformatics familiarity to recognize out-of-range pipeline parameters, and 21 CFR Part 11 discipline to maintain the controlled versioning that turns a sequencing output into a submission artifact.
Site activation speed is the First-Patient-In lever. A specialist clinical operations team compresses the contract-to-FPI cycle by managing site startup, CTMS administration and data query resolution with the scientific literacy to keep the data integrity chain intact from the first patient visit.
Why does every $1 of bad data cost $10 to correct downstream?
Bad Data is any data point that appears correct at generation but introduces an error that compounds through the pipeline and surfaces as a regulatory deficiency at submission. The correction cost is non-linear: ~$1 at the point of generation, $10–$22 at NDA or BLA submission. The Scientific QC layer catches errors at source, before the multiplier compounds.
Legacy manual research ops vs. the Agentic Discovery standard.
The competitive delta between a legacy 2024 manual baseline and the PITON-Global-vetted 2026 standard — across nine dimensions that determine time-to-market, data integrity and inspection readiness.
How an oncology biotech cleared its eTMF debt and accelerated IND filing by 11 weeks.
A documented Q4 2025 engagement: a US-based early-stage oncology biotech with two active IND programs, deploying an 18-specialist Philippine discovery operations team across eTMF, genomics annotation and clinical site support.
We had been running our WGS annotation in-house with a team that understood genomics but had no bioinformatics pipeline QC training. Our metadata error rate was 8.1% — a number we had accepted as normal. PITON-Global’s Scientific QC layer reduced it to 0.4% in 45 days and identified that three of our prior sequencing runs had pipeline parameter violations that had gone undetected. We avoided what would have been a catastrophic data integrity finding at our IND submission.
One line, one dataset — a genomics-QC-only deployment, measured.
BT-071 proves the three-line architecture; BT-078 proves the entry point. A program with a clean eTMF doesn’t need a discovery-ops transformation to stop contaminating its dataset — one layer, placed on the pipeline where the Bad Data multiplier starts, converted an accepted-as-normal error rate into a caught-at-source one in a quarter, and surfaced latent violations before the IND rather than at it. Debt is cleared where it accrues: one dataset at a time.
How the three-layer architecture converts research support into an accelerant for the lab-to-clinic timeline.
A three-layer system built for biotech innovators — a Research Intelligence Layer that ingests lab data, CTMS events and eTMF signals in real time; an Agentic Quality Layer where Scientific QC Specialists and AI deliver 99.5% data accuracy and 99% eTMF completeness; and a 21 CFR Part 11 Data Sovereignty Fabric that turns research outputs into regulatory-grade evidence.
Two biotech-specific failure modes that cause generic BPO to generate Research Debt rather than clear it.
The Scientific QC Gap and the Research Support Debt Blind Spot are specific to R&D outsourcing and cannot be resolved by traditional BPO profiles. Both generate the Research Support Debt they were hired to eliminate. Both are auditable before contract execution.
The $2.8M Runway Paradox: underfunding research documentation is the most expensive decision in early-stage biotech.
Early-stage biotech runs on a consistent logic: every dollar that does not go to lab research or clinical development is a dollar not advancing the discovery. That logic produces chronically underfunded documentation — and the paradox. The eTMF that is 34% incomplete at the IND window required $180K per year to maintain at 99% completeness. The delay that incomplete eTMF generates costs the company $2.8M in runway at a typical burn rate. The $180K investment prevents the $2.8M loss — competitive not at the experiment level, but at the company-survival level.
The Bad Data multiplier makes the arithmetic more asymmetric for genomics-intensive programs. A WGS program across a 120-patient cohort with a 7.4% metadata error rate is systematically contaminating a $2.4M dataset. At $20K per genome, 8–10 invalid samples are $160K–$200K in resequencing, plus the timeline delay and investigator damage. The Scientific QC layer that prevents the error costs $0.40 per sample to operate.
The cheapest column below generates the $10-to-fix errors. That is why it looks cheap.
Procurement opens with cost-per-seat, so we publish it — then run it against the only number that moves an early-stage P&L: the Bad Data multiplier.
Illustrative projection at standard role mix; the fully-loaded labor delta runs roughly a third below an equivalent onshore build — but on this page the labor delta is the small number. The same narrow band as our pharma practice, and for the same reason — biotech roles carry the bioscience-literate premium end to end, and on this page the dividend is built on the Bad Data error that never reaches NDA, not on seat arbitrage. It runs on the same catch-it-at-source quality architecture documented across our pharma and healthcare operations, tuned here to genomics metadata and eTMF completeness. We confirm exact figures — labor line and full Discovery Dividend — against your modality, cohort size, and systems.
Indicative 2026 rates — the science-literate premium in two columns, not a blend.
The spread is the Scientific QC Gap with a price on it. A bioscience-literate specialist who can file to the correct DIA TMF zone or apply ACMG criteria prices 50–90% above the generic equivalent — and a quote at the generic band for a genomics or eTMF role is how you buy the 74% who hired to general science-grad profiles with no domain training.
The rows with no generic equivalent are the point — DIA TMF filing and ACMG annotation are hired, not trained on after onboarding, which is why 74% of providers claiming biotech capability failed the domain assessment (PITON-Global Q2 2026 biotech audit cohort, n=100). Rates confirmed per engagement against modality, cohort, and systems.
Price my role mix against the domain standard →Where Discovery Velocity doesn’t fit — and where the science call always sits.
The fastest way to generate the data-integrity finding this page audits against is to force a bioscience-literate, Part 11-validated operation into work it was never built for — or to let it make a call it must never make. So before the shortlist, the disqualifiers.
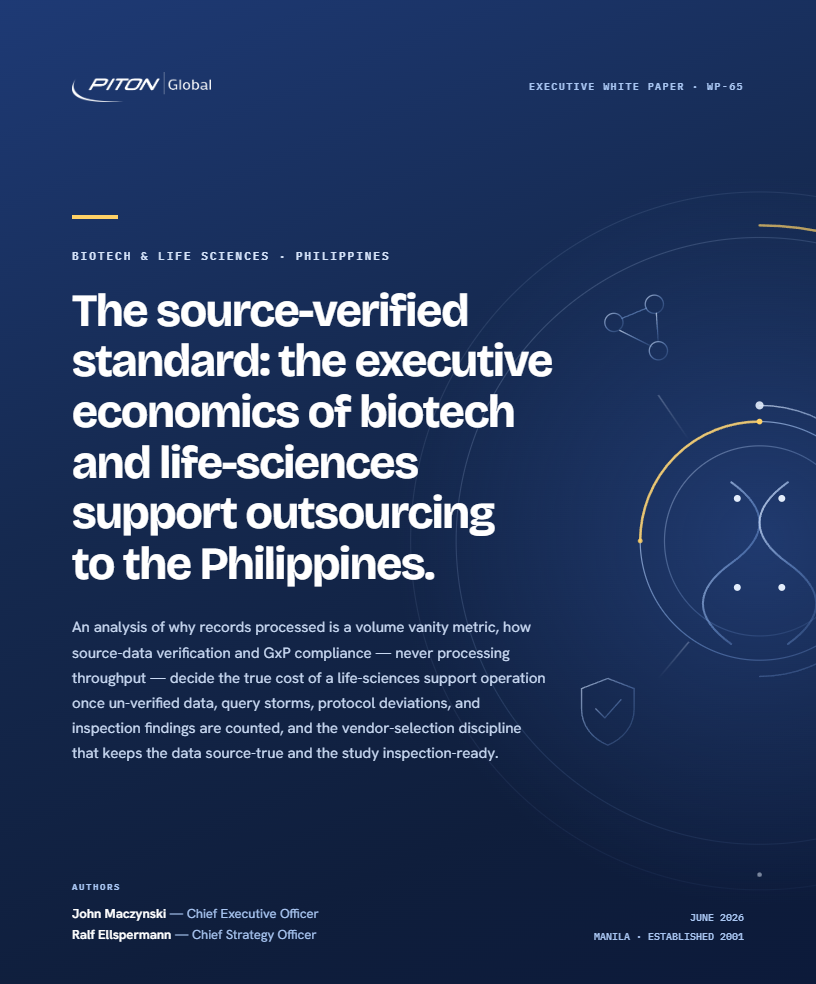
The source-verified standard: the economics of biotech & life-sciences support outsourcing.
Why records processed is a volume vanity metric, how source-data verification and GxP compliance — never processing throughput — decide the true cost of a life-sciences support operation once un-verified data, query storms, protocol deviations and inspection findings are counted, and the vendor-selection discipline that keeps the data source-true and the study inspection-ready. Part of PITON-Global’s Executive White Paper Series, by John Maczynski and Ralf Ellspermann.
What biotech leaders ask before they outsource.
In-depth answers to the questions that decide a biotech engagement — from the principals who run them.