LLM TRAINING & FINE-TUNING OUTSOURCING SERVICES PHILIPPINES

Pre-training gave your model knowledge. Human feedback gives it behavior — and the behavior is what ships.

SFT and instruction data, RLHF and reward modeling, red-teaming, evaluation and agentic oversight — delivered by Philippine-based alignment specialists whose judgment becomes your model’s judgment, because in this work a careless rater isn’t a bad data point: it’s a preference the model keeps, permanently, at every scale you ever run it.

Manila, Cebu & Davao delivery SOC 2 Type II / ISO 27001 certified ISO/IEC 42001-aligned AI governance
LABEL QUALITY · THROUGHPUT Q2 2026
Inter-rater reliability
96%
Gold-set pass rate
97%
Labeling cost reduced
66%
Careless feedback is the real expense. Find the team whose judgment your model can keep.
PLATFORMS & STANDARDS
Label StudioScale AILabelboxSuperAnnotateCVAT / ArgillaSageMaker Ground TruthSnorkel FlowISO 27001SOC 2
22Vetted LLM Training
Partners
SFT and instruction teams measured on example quality, not volume.
180K+Rubric-Graded Eval Items
Scored / Week
SFT, instruction and preference data across domains and languages.
8Gold-Standard
Delivery Hubs
ISO 27001-aligned operations with consensus-label QA.
A CARELESS PREFERENCE IS THE REAL COST · 2026

In AI, a careless preference pass or an unprotocoled probe doesn’t cost you a ticket — it bakes bias into the model, corrupts the eval and ships a worse product. Fine-tuning data is a model-quality function here, scored on label accuracy and agreement, not throughput alone.

01THE ALIGNMENT LOOP ENGINE

Four stations, run round after round — the model gets better because the signal does.

Alignment isn’t a dataset — it’s a cadence. 96% inter-rater reliability sustained across 2025–26 alignment programs (LT-064: hallucinations −63% on regulated queries).

01 · SFT & INSTRUCTION DATA

Instruction-response pairs, expert demonstrations, multi-turn dialogue, domain instruction sets. The control: every demonstration written to rubric and consensus-reviewed — the model imitates what it’s shown, so what it’s shown is QA’d like it matters, because it becomes the model.

GOVERNING METRIC · demonstration acceptance rate 94%
02 · RLHF & REWARD MODELING

Preference comparisons at scale, reward-model data, ranking with written rationales. The control: raters don’t just pick A or B — they can defend why, and calibration scores the reasoning, not just the agreement; an agreeing pool that can’t articulate why is consensus by coin-flip.

GOVERNING METRIC · inter-rater reliability 96%, rationale-quality sampled
03 · RED-TEAM & SAFETY EVALUATION

Controlled adversarial probing against your safety policy: jailbreak attempts, policy-violation elicitation, harmful-capability probes — defensive by design, under documented protocols, findings routed to your safety team for hardening, never published, never repurposed. The control: every probe logged with method, result, and severity — the finding file your safety case cites.

GOVERNING METRIC · findings documented to protocol, 100%
04 · EVALUATION & BENCHMARKING

Rubric-graded scoring for helpfulness, factuality, and safety; side-by-side comparisons; hallucination auditing; human-eval gold sets; regression QA across checkpoints — because a fine-tune that improved the target and quietly broke three other behaviors is a regression wearing a win.
GOVERNING METRIC · eval reproducibility on repeated items 98%
→ RE-TRAIN, EVERY ROUNDThe loop’s output feeds the next checkpoint; the raters re-calibrate against the new model’s failure modes. Alignment isn’t a dataset — it’s a cadence.
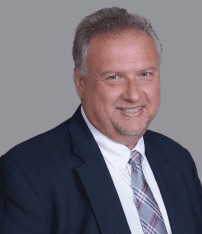
John Maczynski
CEO · AI ALIGNMENT AUTHORITY

“In alignment, your raters and your model are the same conversation. A careless preference doesn’t annoy a user — it becomes the model’s judgment and ships as behavior at every scale you run it. That is why calibration and rationale quality, not items-per-hour, are the only metrics that matter here.”

John Maczynski · CEO, PITON-Global · 40-Year Global BPO Veteran
FINE-TUNING & DOMAIN ADAPTATION

Domain SFT and eval sets for regulated verticals — legal, medical, financial, code — staffed by the credentialed SME bench our AI Data page documents (cross-linked, not retold), plus prompt libraries and behavior QA across model versions: the regression harness that catches what the new checkpoint broke.

AGENTIC OVERSIGHT & GOVERNANCE

Agent-behavior testing under scripted and adversarial scenarios, tool-use validation (does the agent call what it should, and only what it should), guardrail verification, and documented human oversight of autonomous behavior — the evidence file for the question every enterprise deployment now gets asked: who is watching the agent, and can you prove it?

MULTILINGUAL ALIGNMENT

Cross-lingual preference and safety data by native-speaker rater pools — because a model aligned in English and deployed in twelve languages is aligned in one language and lucky in eleven.

02A CLICK FARM VS. A GOLD-STANDARD DATA TEAM

A click farm vs. a data team that protects model quality.

Seven dimensions, read as risk vs. protection — the exposure a click farm creates against what a gold-standard data operation defends.

Click farm
Gold-standard data team
Label Quality
Single-pass clicks
Consensus, >95%
Edge Cases
Guessed, mislabeled
Adjudicated & resolved
Safety
Ignored
Red-teamed
Researchers
Black-box vendor
Embedded data partner
Security
Ad-hoc
ISO 27001, audit-ready
Metric
Labels per hour
Label quality & agreement
Coverage
Business-hours
24/7 follow-the-sun
03RADICAL TRANSPARENCY

You keep the weights, the constitution, and the release call. We supply the judgment — never the decision to ship.

01
The model, the safety policy, and every deployment decision are yours — in the SOW.
We generate signal and evidence against your rubrics and your constitution; where the rubric is ambiguous, the ambiguity is documented and routed to your policy team, never resolved by rater vote. A vendor whose raters quietly interpret your safety policy is a vendor writing it.
02
Red-teaming is defensive, protocoled, and confidential — stated flatly, because your safety team will look for this sentence.
Probing runs under controlled, documented protocols against your policy; findings route to your team for hardening; methods and results are covered by NDA and never repurposed across clients. We red-team to make the model safer, and the protocol file proves it.
03
The clean room covers weights, prompts, and outputs.
The zero-possession architecture — documented in full on our AI Data page; one architecture, two theaters, cross-linked not retold: streamed sandboxes, no local residence, session-level audit. For a lab, the checkpoint never leaves your perimeter — our raters see outputs through glass.
04
Territory, stated on-page — and rater pools cap where calibration holds.
Our AI Data page owns the training data — annotation, labeling, collection; this page owns the behavior — SFT, RLHF, red-team, eval, oversight. Two siblings, one border, each pointing at the other by name. And high-reasoning work has a lower ceiling than labeling: rationale review and drift-checking don’t survive stretched spans — programs cap accordingly; scale comes from calibrated benches, never crowd overflow.
A shortlist that includes “no” is the only kind worth having.
04THE MATH OF DATA DONE RIGHT

Where does the 6.6× return come from when the behavior ships right?

From four streams a per-item rate ignores: retraining runs avoided, incident cost avoided, launch-delay weeks recovered, and conformity-evidence value with reasoning-tier arbitrage. The cheapest incident is the one a red-team found first — and the conformity file that was built as the work happened.

Retraining Runs Avoided
$1.2M – $2.2M
Incident Cost Avoided (probe findings priced)
$1.4M – $2.6M
Launch-Delay Weeks Recovered
$0.6M – $1.3M
Conformity-Evidence Value & Tier Arbitrage
$0.8M – $1.5M
TOTAL ANNUAL NET BENEFIT150-ANNOTATOR DATA PROGRAM
$4.0M – $7.6M
6.4×
Documented return
01
Label Quality — Primary Driver
Bad preference data baked into a checkpoint is compute spent twice — calibrated pools and rationale-scored RLHF keep the retraining budget for planned rounds, not repairs.
02
Quality — Model Protected
Every red-team finding hardened pre-launch is a production incident that never ran — the probe file below prices the difference.
03
Iteration — Compressed
Rubric-graded evals and regression QA cut checkpoint-iteration cycles by weeks — and the oversight trail ships audit-ready, not rebuilt retroactively.
ENTITY PROOF · Q4 2025–Q2 2026
63%
Hallucinations on regulated queries
The healthcare AI team behind LT-064 moved its alignment loop to PITON-Global. Total 12-month net benefit: $2.4M against a $380K engagement cost — a 6.3× return.
25K eval items/wk · Manila, Cebu & Davao · calibrated pools
CLIENT STORY · ENGAGEMENT LT-064 · ENTERPRISE AI

How a Healthcare AI team cut hallucinations on regulated queries 63% — and put the eval trail in front of its auditors.

A clinical LLM was hallucinating on exactly the queries that mattered — medical questions where a confident wrong answer is a liability, not a bug.

−63%
hallucinations,
regulated gold set
+9 pts
factual accuracy,
4 checkpoints
as-filed
oversight trail
passed review
THE CHALLENGE

The team had benchmarks but no rubric-graded human eval, thin domain SFT, and no defensible answer to the compliance question: who checked this model’s behavior, and against what standard?

WHAT WE SOURCED

A calibrated alignment pod: domain-SME raters building 12K gold-standard SFT demonstrations against the client’s rubric, an RLHF pool generating preference data with written rationales, rubric-graded eval on every checkpoint, and a documented oversight trail mapped to ISO/IEC 42001 — the evidence file, built as the work happened.

THE OUTCOME

Hallucination rate on the regulated-domain gold set fell 63%; factual-accuracy scores rose 9 points across 4 checkpoints; and the oversight documentation passed the client’s conformity review as-filed.

“The hallucination drop got the headlines internally, but the eval trail is what got us through review. For the first time we could hand auditors the rubric, the raters’ agreement scores, and every checkpoint’s gold-set results — that documentation is what made the model shippable, not just better.”

— Head of AI, identity withheld under NDA
FOR THE HEAD OF AI / ML How many model defects traced back to bad labels last quarter?
05PRICING TOPOGRAPHY · 2026 RATE CARD

Indicative 2026 rates — priced by reasoning tier, because a preference rater and a red-teamer are not the same seat.

CORE ROLERATE (USD/HR)OPERATIONAL PROFILETIER
SFT data specialist$10–$15Instruction-response pairs, demonstrations to rubric.R
RLHF / preference rater$11–$18Comparisons with written rationales, calibrated pools.R
Model evaluation analyst$12–$19Rubric grading, factuality/safety scoring, regression QA.R
Multilingual alignment rater$12–$19Cross-lingual preference & safety, native-speaker pools.R
Agentic-oversight specialist$13–$21Agent-behavior testing, tool-use & guardrail validation.C
Red-team specialist$14–$23Adversarial probing under documented defensive protocols — the finding file your safety case cites (station 03).NO GENERIC
EQUIVALENT
Domain-SME rater (medical / legal / code)$15–$25Credentialed judgment on regulated-domain SFT and eval — the hard prompts answered by someone qualified to.NO GENERIC
EQUIVALENT
Calibration / QA lead$15–$23Inter-rater reliability, gold standards, drift-checking.QUALITY
Program lead$17–$26Loop governance, checkpoint cadence, client reporting.LEADERSHIP

The two premium rows have no commodity equivalent because a click pool staffs neither: safety gets an output filter and hard domains get confident guesses. Rates confirmed per engagement against program mix.

Price my alignment loop by reasoning tier
THE PROBE FILE · ENGAGEMENT LT-071 · RED-TEAM ONLY

Red-team only — 6 weeks of controlled adversarial probing before the release. Every finding was a production incident that never ran.

CLIENT ENTITY

AI product team, release candidate frozen, 9 weeks to launch. Identity withheld under NDA.

PRE-DEPLOYMENT BASELINE

The model passed its benchmarks and its team’s informal probing — which is what every model does right before a user finds the jailbreak. No structured adversarial program had run; the safety case rested on output filters and optimism. The launch question nobody could answer with evidence: what does this model do under pressure it hasn’t seen?

THE INTERVENTION

A red-team-only engagement — no training data, no fine-tuning, probes only. 12 specialists ran the documented protocol against the client’s safety policy: jailbreak families systematically enumerated, policy-violation elicitation across 14 harm categories, multilingual probe coverage (the aligned-in-one-language trap, tested), tool-use abuse scenarios for the agentic surface, and regression probes against the previous version’s known findings. Every probe logged — method, transcript, severity, reproduction steps — and findings delivered as a hardening queue, ranked.

6 WEEKS, MEASURED
METRICFOUNDHARDENED PRE-LAUNCHWHAT IT WAS
Distinct failure modes surfaced061Production incidents that never ran
Severity-critical findings07The headlines that never printed
Multilingual-only failures019Aligned in English, lucky in eleven — tested
Findings reproducible by client100%Evidence, not anecdote
STRATEGIC INSIGHT

The flagship builds behavior; this engagement pressure-tests it — the audit family’s seventh member, and the only one where the object is behavior and the tense is pre-emptive: every other member audits what exists; the probe file audits what would happen, under adversaries who haven’t arrived yet. The first row is the entire sale: every finding is an incident that never ran, and the difference between a red-team finding and a production incident is who found it first — and whether the discovery came with reproduction steps or a news cycle.

06GOVERNED TO THE STANDARDS BUILT FOR THIS WORK

EU AI Act human-oversight requirements — the documented HITL layer, produced as evidence per engagement · ISO/IEC 42001 — AI-management-system alignment for the loop’s governance · SOC 2 Type II / ISO 27001 — certified, stated plainly · GDPR with PII controls on all human data · the zero-possession clean room covering weights, prompts, and outputs.

FOR THE SAFETY TEAMThe oversight trail is a deliverable, not a byproduct — you can put it in a conformity file.
078-WEEK AI-DATA STAND-UP

A gold-standard data team live in 8 weeks — quality proven before scale.

A gated stand-up. Scale begins only after consensus QA sign-off and a calibration run that clears your gold-set target.

01
Wk 1–2
Rubric & Pipeline Mapping
Label Studio/Labelbox connected, pipeline mapped, rubric and gold set designed, agreement baselined by audit.
02
Wk 3–4
Team & Calibration Build
Annotators and raters recruited and trained; rubric built; calibration run against the gold set with adjudication workflows in place.
03
Wk 5–6
Parallel Run
A calibration batch runs with daily agreement reviews, and label quality must validate to the gold-set target before any scale-up.
04
Wk 7–8
Cutover & Govern
Volume ramps in phases under a live agreement, quality and throughput dashboard, with monthly business reviews — closing in Gold-Standard certification.
08THE LABEL-QUALITY TEST · WHAT TO VERIFY

Before a vendor fine-tunes on your data, can they prove the examples are right?

Three controls separate a gold-standard data team from a click farm — and each is demonstrable before you sign. In AI, the cost of getting one wrong is a biased model and a corrupted eval.
01
Consensus QA on Every Batch
Single-pass clicks ship mislabeled data and bias. Serious teams put every batch through multi-pass consensus QA, intercepting errors before they touch training.
VERIFY: Request the inter-annotator agreement and gold-set pass rates
02
Adjudication, Not Guessing
A farm that guesses edge cases has already failed. Teams worth engaging route hard cases to rubric-based adjudication, holding label quality exactly where it matters.
VERIFY: Request the edge-case adjudication workflow
03
Secure, Not Leaky
Data work on personal devices leaks IP and PII. Gold-standard operations run on locked-down ISO 27001 infrastructure, audit-trailed end to end.
VERIFY: Confirm secured infrastructure, not personal devices
THE LINE-CRITICAL ARCHITECTUREhow each risk is designed out
Consensus QA
Every batch is labeled and independently verified by consensus, holding agreement above 95% and catching errors before training.
Gold-Set Calibration
Calibration against the gold set is continuous rather than spot-checked, sustaining label quality across millions of items.
Secure, Audited Operations
Work happens on ISO 27001 infrastructure under a complete audit trail — your data and IP stay put.
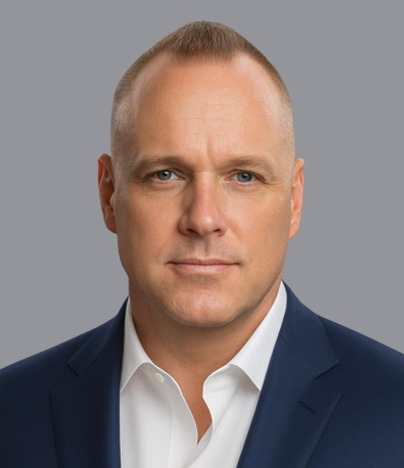
Ralf Ellspermann
CSO · AI DATA OPERATIONS

“Give a prospective alignment partner a hundred prompts with known failure modes salted in. A calibrated pool flags and escalates nearly all of them. A click pool rates right past them, and three checkpoints later the model has learned the wrong judgment and your eval can’t tell you why.”

Ralf Ellspermann · CSO, PITON-Global · 25-Year Philippine BPO Veteran
FOR AI & ML LEADERS

A bad label you can’t see is a model defect you’re about to ship.

Tell us where your data pipeline strains — annotation volume, RLHF quality, eval reliability, red-teaming — and we’ll hand you 6–10 vetted AI-data providers, every one of them tested against a gold-set label exercise before earning a place on your shortlist.

Get my AI-data shortlist
Vendor-neutral · no cost to you · 24-hour response guarantee, red-team scoping estimate included · prepared and presented by John Maczynski, CEO
WP-49 LLM Training & Fine-Tuning Outsourcing white paper cover
PDF · 14 PAGES
09WHITE PAPER WP-49 · LLM TRAINING & FINE-TUNING · JULY 2026

The capability-taught standard: the economics of LLM training & fine-tuning data outsourcing.

Why examples labeled is a volume vanity metric, how instruction quality and eval-verified taught capability — never labeling throughput — decide the true cost of a fine-tuning dataset once wrong demonstrations, off-policy answers, reward hacking and eval regressions are counted, and the vendor-selection discipline that teaches the model what you actually wanted. Part of PITON-Global’s Executive White Paper Series, by John Maczynski and Ralf Ellspermann.

14 pages16-min readMaczynski & Ellspermann
IN THESE PAGES
The volume mirage: examples labeled versus capability taught, read on the eval.
The SFT contract: demonstrate it correctly, cover the distribution, verify on eval.
Case study FT-063: a 44-seat SFT-data operation re-based on taught capability — 6.4× first-year ROI.
Read the white paper (PDF) Free · no gate · published July 2026
11ANSWERED BY OUR PRINCIPALS

The questions AI teams put to us before outsourcing data work.

Detailed answers on what decides a training-data engagement, from the two principals accountable for it.

How do you guarantee label quality at the scale a model needs?+
Batches go through multi-pass consensus labeling on a detailed rubric, calibrated continuously against the gold set, with hard edge cases adjudicated. Inter-annotator agreement stays above 95 percent — the threshold where data genuinely improves a model instead of quietly mis-teaching it.— Ralf Ellspermann, CSO
What does outsourcing annotation and RLHF actually save us?+
Cost per label usually drops 50 to 70 percent against onshore, and iteration cycles shorten alongside. The larger economics are in rework you never do: consensus-checked data heads off the corrupted training runs and untrustworthy evals that would demand re-labeling and re-training weeks on.— John Maczynski, CEO
Can annotation volume scale quickly against a model deadline?+
Yes. Trained annotator and rater capacity surges within days and contracts as the project winds down — you buy throughput, never idle headcount. Consensus QA and gold-set calibration operate identically at any volume, so deadline pressure never erodes quality.— Ralf Ellspermann, CSO
How is our proprietary data and IP protected?+
Everything executes on ISO 27001 infrastructure — locked-down access, personal devices banned, no local storage, audit trails throughout. Data access is scoped to project and annotator, actions log automatically, and nothing exits the secured environment at any stage.— Ralf Ellspermann, CSO
How do you handle ambiguous or genuinely hard edge cases?+
Difficult items escalate to senior reviewers for rubric-based adjudication — never left to the guess of whoever happened to draw them. Disagreement patterns feed rubric refinement, so the guidelines improve continuously over the life of the project.— John Maczynski, CEO
Can you support RLHF, preference data and model evaluation, not just labeling?+
Yes. The full pipeline is in scope: collection and curation, annotation, RLHF and preference ranking, blind evaluation, red-teaming. Rater calibration and adjudication keep the preference signal consistent, giving your reward model clean, low-noise training data.— John Maczynski, CEO
Will your teams work in our tools and platforms?+
Yes. Teams operate natively across Label Studio, Labelbox, CVAT, SuperAnnotate and whatever internal tooling you run. Your pipeline stays as-is — we integrate with your task queues and review systems, preserving both throughput and audit trails.— Ralf Ellspermann, CSO
Can you support multilingual RLHF across languages?+
Through continuous gold-set calibration rather than occasional spot checks. Raters are checked against known-correct items for the duration, drift surfaces early, and adjudication settles disagreement — quality stays flat across the dataset instead of decaying with volume.— Ralf Ellspermann, CSO
Which data work should we outsource first?+
Lead with high-volume, tightly specified annotation and evaluation — rubric-driven consensus QA pays back there immediately and measurably. Subtler RLHF and red-teaming streams follow once guidelines, the calibration loop and security controls have proven out on that base.— John Maczynski, CEO
How do you prevent annotator drift over long-running RLHF programs?+
Against inter-annotator agreement, gold-set pass rate, label accuracy and throughput, surfaced in a live dashboard. Labels-per-hour is never the optimization target: speed without agreement yields data that looks productive while degrading the model it was meant to help.— Ralf Ellspermann, CSO
Authorship, Review & Benchmark Verification
Authored by:
Ralf Ellspermann
Ralf Ellspermann
Chief Strategy Officer of PITON-Global
Two Decades Building and Advising Award-Winning Philippine BPO Operations

Ralf benchmarks fine-tuning floors on preference-data quality and RLHF-pipeline discipline.

View full bio  →
Verified by:
John Maczynski
John Maczynski
CEO of PITON-Global
Former Global EVP of the World’s Largest Contact Center · Four Decades of Outsourcing Experience

John reviews the data-security posture and commercial terms behind each LLM-training program on this page.

View full bio  →
Last Reviewed & VerifiedJuly 27, 2026

Re-audited as SOC 2 Type II and emerging AI-governance obligations evolve. Every benchmark on this page is held to PITON-Global’s internal vetting standard.

error: Content is protected !!
Inquire Now