A model can only be as reliable as the humans who labeled its examples, which is why the teams behind human data work for AI labs are judged on consistency far more than on speed. Data annotation quality is not a trait a vendor either has or lacks; it is a system of guidelines, calibration, review and measurement that teams across the Philippines, from Manila to Cebu, run every day. This post explains how that system is built, what to measure, and where it usually breaks.
What data annotation is, and why accuracy decides the model
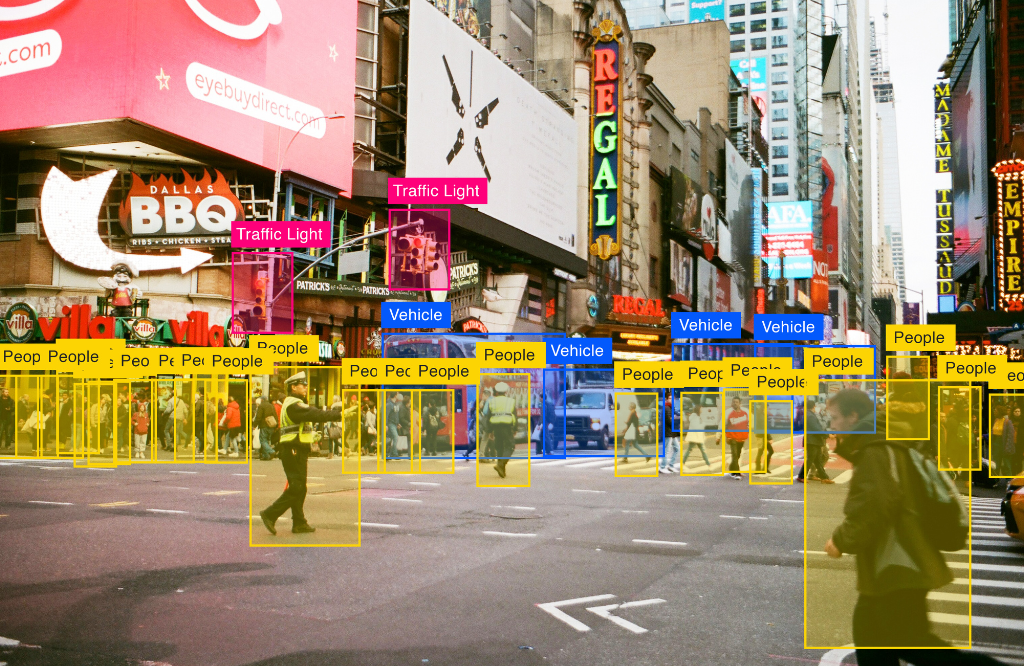
Annotation is the labeling or tagging of raw data so a machine-learning model can learn from it: marking objects in images, transcribing audio, tagging the sentiment or intent of a sentence, or ranking two model answers by quality. Every label becomes a lesson the model repeats.
That is why small error rates matter. A model trained on inconsistent labels learns the inconsistency. An evaluation set with mistakes gives a false reading of how good the model is, and a preference dataset with careless rankings pushes a fine-tuned model toward the wrong behavior. In each case the error is hard to spot later, because the model looks confident either way. Quality has to be built in while the labels are made, not inspected in afterward.
The guideline comes first
Most labeling errors trace back to an unclear instruction, not a careless annotator. A strong guideline defines every class, shows correct and incorrect examples, and says exactly what to do with the ambiguous cases that will certainly appear.
- Define each label in plain language, with at least one positive and one negative example.
- List the known edge cases and the ruling for each, such as a partly hidden object or a sarcastic compliment.
- Say what annotators should do when nothing fits: skip, flag or escalate.
- Keep a dated change log, so everyone knows which version of the rules a batch was labeled under.
Good Philippine vendors treat the guideline as a living document. Their team leads collect the questions annotators raise each week and turn the answers into new rulings, so the same confusion does not recur across hundreds of people.
Calibration, consensus and gold sets
Three tools keep a large team labeling the same way: calibration before production, consensus on hard items, and a gold set that every person is scored against. Together they turn individual judgment into a shared standard.
Calibration
Before touching live data, each annotator labels a practice batch and is scored against reference answers. Those below the agreed threshold retrain; those above it move to production. Calibration sessions then continue weekly, walking the team through recent disagreements and the rulings that resolved them.
Consensus labeling
For items where judgment varies, two or three annotators label the same item independently. Where they agree, the label stands; where they differ, a senior reviewer or adjudication lead decides. It costs more per item and is worth it on the hard minority of a dataset, where most model errors originate.
Gold sets
A gold set is a collection of items with verified answers, seeded silently into normal work. Because annotators do not know which items are gold, their score on them is an honest measure of accuracy. A good gold set is refreshed often and weighted toward the edge cases, not the easy items.
Measuring agreement and catching drift
Quality you cannot measure will drift. The two numbers to track are inter-annotator agreement (how often independent annotators give the same label) and gold-set pass rate (how often they match the verified answer), reported by task and by modality rather than as one blended figure.
The difference a disciplined team makes shows up in those numbers. Across 2025–26 vetted engagements, programs reached 96% inter-annotator agreement and a 97% gold-set pass rate; in one case, a foundation-model team moved from a previous vendor at 82% agreement to a 150-person consensus-QA team in Manila at 96%, with label errors down 81%, as documented on our annotation and labeling service page.
Watch the trend, not only the level. Agreement that slides a little each week usually means the guideline has fallen behind the data, new hires were rushed through calibration, or a new edge case has appeared. A weekly quality report that breaks results down by annotator and task lets you catch that drift in days, before it reaches a training run.
Language and domain expertise as quality inputs
Process sets the floor for accuracy; the knowledge annotators bring sets the ceiling. That is where expertise from the Philippines comes in, especially on text, speech and specialist data.
English is an official language in the Philippines, and annotators there tend to know North American idiom, humor and cultural references well. That helps on the tasks where meaning is subtle: sentiment, intent, sarcasm, toxicity and the tone of a chatbot reply. Our guide to human judgment in natural language processing work goes deeper on those text tasks.
Domain knowledge matters just as much. The Philippines trains large numbers of health and technical professionals, and many now work in data roles: nurses and pharmacists review clinical data, engineers review industrial and sensor data, and accountants review financial documents. On simulation-heavy work, such as the 3D asset and sensor labeling described in our piece on annotation for industrial digital twins, that engineering background is often what separates a usable label from a plausible-looking one.
Where quality programs break down
Most failures come from a few predictable causes, and each has a known fix. Plan for them before the first batch rather than after the first bad model.
- Skills lag the work. Tasks change quickly, from bounding boxes to preference ranking and red-teaming. Ask how the vendor retrains existing staff, not only how it hires.
- Ramps outrun calibration. Doubling a team in two weeks almost always lowers agreement. Insist that every new annotator passes calibration first.
- Feedback loops are too slow. If your ML team answers annotator questions once a week, errors pile up in between. Agree a response window and an overlap shift for live questions.
- Security shortcuts. Quality work is worthless if the data leaks. Expect audited sandboxes where nothing is stored locally, SOC 2 Type II and ISO 27001 controls, and full access logs.
The time-zone setup helps with the feedback problem. Teams in the Philippines commonly label while North American ML teams sleep, and a short overlap shift at the start of the US day handles escalations, so questions raised overnight are answered before the next batch starts.
Choosing a vendor on evidence, not promises
Ask every candidate to prove its quality system on your data. A paid pilot with two or three Philippine vendors on a representative slice, scored against your own gold set, tells you more than any capabilities deck.
In the pilot, compare agreement by task, gold-set pass rates, how quickly edge-case questions were answered, and how the vendor updated the guideline in response. Then write those measures into the contract, with rework at no charge when a batch falls below the threshold. Our overview of scaling AI training with expert annotators covers the commercial side of that contract in more detail.
Frequently asked questions
What is a good inter-annotator agreement target?
It depends on the task. Simple object tagging should reach very high agreement, while subjective tasks such as sentiment or preference ranking will naturally sit lower. Set targets per task during the pilot, based on what your best annotators achieve, rather than one number for the whole program.
Who should own the labeling guideline?
You should own the definitions, because they encode what your model needs to learn. The vendor should own the day-to-day upkeep: collecting questions, drafting rulings for your approval and keeping the change log current.
How often should quality be reported?
Weekly at the task level, with a fuller review each quarter. Weekly reports catch drift early, and quarterly reviews are the place to reset targets, retire easy gold items and plan retraining.
Is consensus labeling needed on every item?
No. Use it on the ambiguous minority of items and on anything feeding an evaluation set. Routine items can be single-labeled with sampled review, which keeps cost down without lowering the quality that matters.
PITON-Global is a vendor-neutral advisory that has worked on the ground in Manila since 2001. If you want a shortlist of Philippine annotation vendors whose quality systems hold up under a pilot, we prepare one free and with no obligation.