


One mislabeled frame is a mistake. A thousand is a safety case.
We'll line up six to ten award-winning, mid-sized, fully compliant providers in Manila that specialize in autonomous-vehicle data labeling for your use case and are serving teams like yours right now. Shortlist in 48 to 72 hours. Completely free, no obligation.

Sourced for you, not listed. Free, no obligation.
Your details go to John, nobody else.
Autonomous vehicle data labeling BPO Philippines: quality at scale
Yes, if quality is decided before the first frame is labeled and throughput is managed separately. Vetted Philippine teams work from a detailed guide and a gold set of reviewed examples, run a calibration round before volume ships, and report accuracy by object class and by scenario — night, rain, glare, occlusion, unusual road users — rather than one blended score, with disputed frames routed to an adjudication lead. 2D boxes and video tracking usually share a team; 3D cuboids, sensor fusion and depth get more review time and their own reviewers, because that is where errors cost most to fix. Rare events — emergency vehicles, animals, fallen cargo — are escalated and fed back into the guide. In one PITON-Global engagement (AL-078), a consensus-QA workflow in Manila lifted annotator agreement from 82% to 96% and cut label errors 81%.
When labeling is bought on frames per dollar alone, precision on rare classes quietly falls and the model learns to miss them. Providers here are scored on accuracy per class and scenario, annotator agreement and cost per accepted frame.
AV labeling depends on collected drive data and mapped roads. The teams that collect, map and evaluate usually work together.
Indicative 2026 rates — priced by role, fully loaded per hour.
Compare cost per accepted frame or object, not cost per hour; price 2D, video and 3D work separately. Annotation platform is client-provided or licensed separately. Rates confirmed per engagement.
Scope my labeling program →How autonomous vehicle data labeling outsourcing differs by AV program.
Sensor suite, domain and safety case differ by program, so each labeling team is set up around its own stack.
Urban scenes with dense LiDAR and multi-camera fusion.
Highway scenes, long-range objects and rare events.
Camera-first labeling at production volume.
Low-speed scenes with pedestrians and curbs.
Four label pods — 2D and video, 3D and depth, sensor fusion, and gold-set QA.
Each pod has its own rubric and reviewers and prices separately. Pods scale independently as your data mix changes.
Bounding boxes for object detection — where a new team proves it can follow your class list and tightness rules — and frame-by-frame video annotation that keeps one identity per object from the moment it enters the scene until it leaves.
Cuboids fitted in the point cloud with heading and size set, sparse returns at range and partly visible objects handled by rule, plus depth labels that teach camera-only stacks to judge distance — with accuracy tracked on heading and position as well as class.
Camera, LiDAR and radar aligned into one labeled scene so an object marked in the frame matches the same object in the point cloud and the radar track; calibration and synchronization confirmed first, with clear rules for objects one sensor sees and another misses.
The detailed guide, reviewed gold set and calibration round that precede volume; accuracy reported per class and per scenario; rare events found, escalated and fed back; annotators retrained every time the taxonomy changes; audit trails traced to each dataset release for ISO 26262 evidence.
This page is the data side of autonomous vehicles. The AV page is the whole program.
Use this page for perception labeling at fleet scale; use the autonomous vehicles page for labeling, fleet support and safety validation together; use the robot training data page for point clouds, keypoints and demonstration on robots.
2D and video, LiDAR and depth, sensor-fusion and gold-set QA for AV perception models, inside your labeling platform.
Data labeling, driverless fleet support and safety validation — the full autonomy program, with the remote operators whose decisions become this page’s edge-case batches.
Autonomous vehicles →Point clouds, keypoints and task demonstration for mobile, warehouse, manipulation and humanoid robots — the same skills carried into robotics.
Robot perception training data →
Autonomous Vehicle Data Labeling in the Philippines: LiDAR, Sensor Fusion and Video
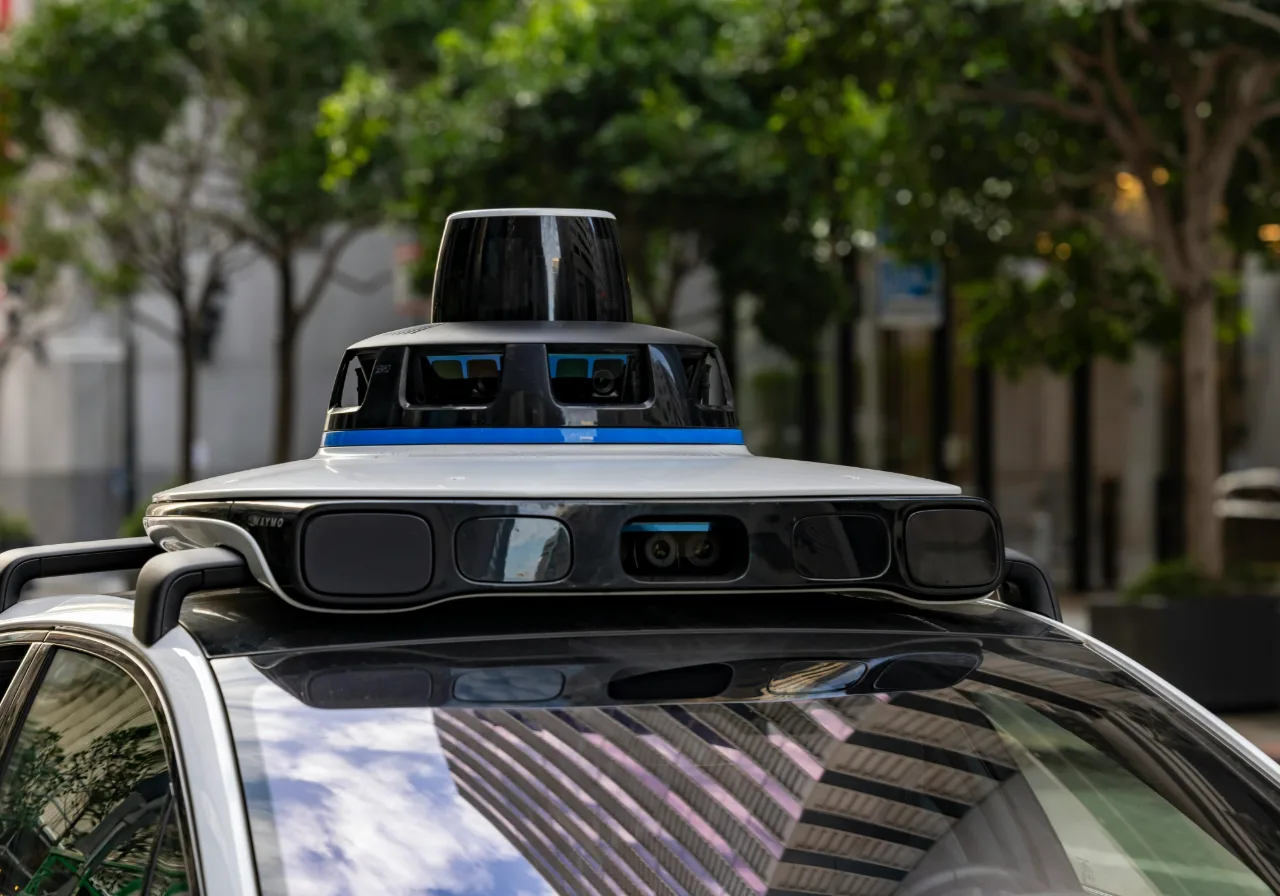
Autonomous vehicle data labeling in the Philippines gives self-driving and driver-assistance programs trained annotators for the sensor data their perception models learn from: camera video, LiDAR point clouds, radar returns and the fused scenes that combine them. It is the data side of our autonomous vehicles hub, and it suits programs whose labeling needs grow with every new city, season and vehicle platform they add.
The quality bar in this work is set by road safety. A pedestrian missed in training data can become a pedestrian missed on the street, so every object must be found, classified and tracked across frames and sensors. Vetted teams in Manila, Cebu and Baguio can run this at volume, around the clock, inside the client’s own labeling platform. For a wider view of the market, see our note on how verified data is fueling the self-driving industry.
The labeling techniques a perception stack needs
Most programs use five techniques, often on the same drive: 2D boxes, frame-by-frame video tracking, 3D point-cloud cuboids, sensor-fusion labels and depth labels. Each needs its own rubric and its own reviewers.
Two-dimensional bounding boxes for object detection remain the entry point, and they are where a new team proves it can follow your class list and tightness rules. Frame-by-frame video annotation adds tracking over time, so every object keeps one identity from the moment it enters the scene until it leaves. Work on still frames and video usually shares a team, since the tracking rules build directly on the box rules.
LiDAR, point clouds and depth
Three-dimensional work is where expert skill matters most and where errors cost most to fix. Annotators fit cuboids to objects in a point cloud, set heading and size, and handle sparse returns at range.
Our guide to 3D point cloud labeling covers the method, including how to treat partly visible objects and reflections. Camera-only programs still need a sense of distance, and depth estimation labeling explains how annotators teach models to judge it. Budget more review time for 3D than for 2D, and track accuracy on heading and position as well as on class.
Fusing camera, LiDAR and radar
Sensor fusion aligns every sensor into one labeled scene, so an object marked in the camera frame matches the same object in the point cloud and the radar track. It is the hardest labeling work in the field and the one that most separates capable teams from the rest.
Calibration and synchronization come first; if the sensors disagree, the annotators cannot fix it. Then set clear rules for objects one sensor sees and another misses. Our guide to sensor-fusion labeling goes deeper, and the same skills carry into robotics, where our planned hub for robot perception training data covers point clouds, keypoints and task demonstration for robots.
Guidelines, gold sets and edge cases
Label quality is decided before the first frame is labeled. Write a detailed guide, build a gold set of reviewed examples, and run a calibration round before any volume ships.
Measure accuracy by object class and by scenario, such as night, rain, glare, occlusion and unusual road users, rather than as one blended score, and route disputed frames to an adjudication lead. Rare events matter most: emergency vehicles, animals, fallen cargo, people in costumes. Ask the vendor how it finds them, escalates them and feeds the decision back into the guide.
Annotators need structured training on your taxonomy, and they need it again every time the taxonomy changes. Our piece on training teams for object detection work covers how to onboard and recalibrate them. In one PITON-Global engagement listed on our annotation service page (AL-078), a foundation-model team that moved to a consensus-QA workflow in Manila lifted agreement between annotators from 82% to 96% and cut label errors 81%, measured across 2025–2026.
Protecting road data
Road footage shows faces, license plates, homes and routes, so it must be handled as personal data from the start. Anonymize faces and plates where the task allows, and keep raw data inside a controlled environment.
Require SOC 2 and ISO 27001 controls, zero-possession workspaces where assets stream into audited sandboxes and never sit on local machines, disabled downloads and capture, role-based access and a full session log. Programs working toward ISO 26262 functional-safety evidence should also ask how labeling versions and reviewer decisions are traced back to each dataset release.
What it costs
Indicative 2026 rates on PITON-Global’s data annotation service page put computer-vision and sensor-fusion experts at $14–18 per hour, general annotators at $6–12 and quality and gold-set leads at $14–16, confirmed per engagement against data type and volume.
Compare cost per accepted frame or per accepted object, not cost per hour, because rework on 3D and fused data is expensive and a low hourly bid often hides a high rejection rate. Price 2D, video and 3D work separately. Our pricing guide models team costs by function.
How to choose a vendor
Choose the team that can prove accuracy on your own sensor data, inside your labeling platform, under controls built for road footage.
Run a paid pilot on a representative drive set that includes your hardest scenarios, score it against your own gold set and compare vendors per class and per scenario. Check tool experience with your platform, how the team handles guideline changes and how fast disputed frames are resolved. A gated stand-up takes about eight weeks: rubric and pipeline mapping, team build and calibration, a parallel run, then cutover. Our seven-step vetting framework describes how PITON-Global tests providers before they reach a shortlist, and our wider guide to outsourcing to the Philippines covers delivery hubs and contracts.
Where labeling meets fleet operations
Once vehicles run without drivers, the edge cases arrive live. The remote operators who help a stuck vehicle are also a source of labeled data, if their decisions are returned to the perception team.
Our planned guide to autonomous fleet and remote operations support covers the operations desk, and the data annotation and labeling service covers the wider range of modalities for teams that also label text, audio or medical images.
Hidden champions: the six to ten providers you’d otherwise have missed, lined up in 48 to 72 hours. Judge for yourself. No cost, no obligation.
Frequently asked questions
Build your perception data team with PITON-Global
PITON-Global is a vendor-neutral advisory. Tell us your sensor stack, data volumes and quality bar, and we return a free shortlist of vetted Philippine labeling teams that have already delivered work like yours. Book a no-obligation call to start.
Book a no-obligation call →