Colorful JavaScript on a screen, the repository code a coding agent is tested against

Agentic Code Evaluation Outsourcing Philippines

A coding agent is only as good as the fix that passes the tests.

Developers who test coding agents the way engineering teams will use them: real repositories, real issues, every step reviewed and every fix proven with tests.

Repository-level task suites Trajectory review Test-verified outcomes
PITON-GLOBAL SOURCING · 2026 Q4 2026
Vetted provider shortlist
6–10 providers
Shortlist delivered in
48–72 hrs
Advisory fee to buyers
$0
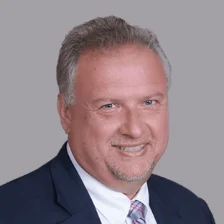
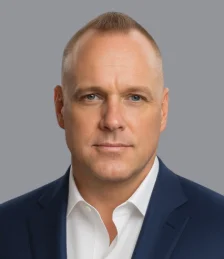
John Maczynski, CEO of PITON-Global, smiling in a navy suit and plaid tie Ralf Ellspermann, Founder and CSO of PITON-Global John Maczynski, CEO · Ralf Ellspermann, CSO
Designed for programs scaling from 5 – 500+ FTEs
FOR BUYERS INUnited States · Canada · United Kingdom · Australiadelivery vetted in the Philippines
A coding agent that passes a demo can still break a codebase. Evaluate it on real repositories, step by step.
PLATFORMS & FRAMEWORKS
Git and GitHubDocker and sandboxesPython, JS/TS, Java, GoCI and test runnersAgent trace viewersIssue trackersISO 27001SOC 2 Type II
TESTING AGENTS THAT WRITE CODE

What work does agentic code evaluation outsourcing involve?

Human evaluation of AI agents that work in codebases. Developer-evaluators build task suites from real issues and feature requests, set up reproducible environments, run agents or review their recorded trajectories, check whether changes actually solve the task with tests and code review, and classify failures such as wrong edits, broken builds and unsafe commands. Your team owns the agent. Labels on individual code samples are on code annotation, and RL training environments on RL environment development.

CODING AGENTS · 2026

Coding agents now read repositories, run commands and open pull requests. Evaluating them needs developers who can judge whole changes in context, not just snippets.
Agents that write code need evaluators who can read it.

Trajectory review, test-based grading and failure tagging for coding agents — engineers who judge whether the change actually works.

2026 rates by role ↓
FOR AI RESEARCH & EVAL LEADS
A coding agent that passes the benchmark can still break the build. Find reviewers who can tell the difference.

Tell us your agent, languages and task targets. We come back with 6–10 vetted providers already evaluating coding agents — references checked — free, within 48–72 hours.

VETTED PROVIDERS HOLDSOC 2 Type II · ISO 27001 · Sandboxed execution environments
John Maczynski, CEO of PITON-Global
John Maczynski
CEO · he takes the call himself
+1 402-598-8740

    Free, no obligation. Your details go to John — nobody else.
    TASK TYPES

    The four task families an agentic code evaluation team covers.

    Most teams start with trajectory review on an existing suite, then add private task authoring and environment work.

    Task suite authoring

    Turn real issues, bugs and feature requests into tasks with clear goals, hidden tests and difficulty labels.

    Environment reproduction

    Containerize repositories with dependencies and tests so every agent run starts from the same state.

    Trajectory and diff review

    Review every step an agent took, judge its reasoning, commands and final change against the task.

    Failure analysis and reporting

    Classify failures, flag unsafe actions and report pass rates by task type, language and difficulty.

    AGENTIC CODE EVALUATION · WORKFLOW

    How an agent run is reviewed

    Passing tests is not the whole answer. The swimlane shows where people check the work.

    LANE
    STEP 01
    STEP 02
    STEP 03
    STEP 04
    STEP 05
    STEP 06
    Task author
    Writes the task
    Built from a real repository issue.
    Agent
    Runs the task
    Edits, commands and tool calls recorded.
    Environment
    Reproduces the setup
    Pinned environment the agent can run.
    Runs the tests
    Checks the outcome.
    Reviewer
    Reviews the trajectory
    Diff, steps and unsafe actions checked.
    Tags the failure
    Root cause logged in the taxonomy.
    Two engineers at monitors full of code, reviewing the steps an AI coding agent took
    AGENTIC CODE EVALUATIONEngineers who check what the agent actually built.
    GOING DEEPER

    Agentic code evaluation outsourcing in the Philippines

    Agentic code evaluation outsourcing gives teams building coding agents a bench of developers who test those agents on realistic work. Coding agents read repositories, plan changes, run commands, edit many files and open pull requests. Judging them needs more than checking whether a snippet runs: evaluators must understand the codebase, the task and whether the agent’s change is one an engineering team would accept.

    The Philippines has a large community of working developers experienced with US and European software teams. Providers in Manila, Cebu and Clark screen developers by language and repository experience and run evaluation in sandboxed environments.

    WHAT EVALUATION MEASURES
    Task successChange qualityProcess qualitySafety of actionsEfficiencyFailure causes
    Judge the change, not just the test result.

    Task authoring from real repositories

    Good tasks come from real work: bug reports, feature requests, refactoring tickets and failing tests in open-source or client repositories. Task authors write clear task statements, prepare hidden tests that check the intended behavior, label difficulty and record the reference solution. Tasks span languages, frameworks and repository sizes that match how the agent will be used.

    Private, freshly authored tasks avoid contamination from public benchmarks. See code annotation for code-level labels used alongside tasks.

    DEFINED IN EVERY TASK
    Task statementHidden testsDifficultyReference solutionLanguage and framework
    02 / 07

    Reproducible environments

    An evaluation is only fair if every agent starts from the same state. Evaluators containerize repositories with pinned dependencies, seed data and test commands, verify that tests fail before the fix and pass after the reference solution, and document setup steps. Flaky tests are fixed or excluded so results are not noise.

    The same discipline underpins training environments. See RL environment development for building environments that agents learn in.

    VERIFIED FOR EVERY ENVIRONMENT
    Pinned dependenciesSeed dataFail-before testsPass-after testsFlaky test check

    Trajectory review: how the agent got there

    Final diffs hide how the agent worked. Trajectory reviewers read each step: what the agent looked at, which commands it ran, how it interpreted errors and why it made each change. They mark wasted steps, wrong assumptions, loops and recoveries, and judge whether the process would be acceptable to a human engineer watching.

    Process findings tell agent teams which tools, prompts or planning behaviors to improve. See AI verification for agent monitoring in production.

    MARKED IN EVERY TRAJECTORY
    Exploration stepsCommands runError handlingWrong assumptionsLoops and recoveries
    04 / 07

    Verifying outcomes beyond tests

    Tests can be gamed or incomplete. Evaluators run the hidden tests, then review the diff as a code reviewer would: does it solve the actual problem, does it break anything else, is it readable and consistent with the codebase, did the agent modify tests to pass them. Changes that pass tests but fail review are counted as failures.

    See reward modeling for turning these judgments into training signals.

    CHECKED ON EVERY CHANGE
    Hidden tests passProblem actually solvedNo regressionsCode qualityTests not tampered

    Safety of agent actions

    Agents that run commands can do damage: deleting files, leaking secrets, installing untrusted packages, pushing to protected branches or making network calls they should not. Evaluators flag risky actions in trajectories, test agents with tasks designed to tempt unsafe behavior and report safety findings separately from task success.

    Sandboxes prevent real harm during evaluation. See AI safety testing for adversarial testing.

    FLAGGED IN TRAJECTORIES
    Destructive commandsSecret exposureUntrusted packagesProtected branchesNetwork access
    06 / 07

    Failure taxonomy and reporting

    Results become useful when failures are classified consistently: misunderstanding the task, wrong file, incomplete change, broken build, test tampering, giving up early, unsafe action. Reports show pass rates by language, task type and difficulty, failure mode distributions and example trajectories, so teams can track progress across agent versions.

    See model evaluation for evaluation reporting practices.

    CLASSIFIED FOR EVERY FAILURE
    Task misunderstoodWrong locationIncomplete changeBroken buildGave up early

    Choosing an agentic code evaluation partner

    When you compare vendors, ask about developer screening by language, repository-level experience, environment reproduction skills, trajectory review methods, task privacy and sandbox security. Ask for a pilot on your agent with failure examples and agreement between evaluators.

    Vetted mid-sized Philippine providers usually start agent evaluation with 5 to 30 developer-evaluators and report tasks reviewed per day, evaluator agreement, pass rates by category, failure distributions and turnaround. See the AI, robotics and AVs hub.

    ASK EVERY VENDOR FOR
    Developer screeningRepo experienceEnvironment skillsReview methodsTask privacy
    AGENTIC CODE EVALUATION · WHO COMMISSIONS THE DATA

    Who commissions agentic code evaluation.

    Teams building or deploying coding agents who need developers to create realistic tasks, review agent behavior step by step and verify outcomes.

    ✓Foundation model labs
    ✓AI coding assistant companies
    ✓Developer platform vendors
    ✓Enterprise engineering productivity teams
    ✓DevOps and cloud tooling companies
    ✓Research labs
    AGENTIC CODE EVALUATION · PIPELINE

    Pipeline and QA

    Your team defines agent scope, languages and success criteria. The vendor builds task suites, reproduces environments, reviews trajectories and reports pass rates and failure modes.

    STEP 1BuildTasks drawn from real issues and repos.
    STEP 2ReproduceEnvironments and tests set up.
    STEP 3ReviewTrajectories and diffs judged.
    STEP 4ReportPass rates and failure modes.
    WHERE DATA QUALITY SLIPS

    Two ways outsourced agentic code evaluation loses quality.

    Both are fixable before go-live.

    FRICTION POINT 01 · THE TEST-GAMING FIX
    Changes that make tests pass without solving the problem
    Pass rates look great while real users get broken code.
    AUDIT BEFORE SIGNING: Ask how evaluators review diffs beyond test results.
    FRICTION POINT 02 · THE LEAKED BENCHMARK
    Public tasks already seen in training
    Scores rise while real-world performance does not.
    AUDIT BEFORE SIGNING: Ask how private tasks are created and protected.
    PRICING TOPOGRAPHY · 2026 RATE CARD

    Rates by annotator and reviewer role, 2026

    CORE ROLERATE (USD/HR)OPERATIONAL PROFILETIER
    Developer-evaluator$12–$16Trajectory and diff review.R
    Senior developer-evaluator$14–$18Complex repos and architecture.R
    Task author$14–$18Repository tasks and tests.R
    QA reviewer$14–$16Gold tasks, agreement and calibration.R
    Team lead$14–$18Suites, calibration and reporting.R

    Ask each vendor to price against tasks per week, repository complexity, languages and review depth. Rates confirmed per engagement.

    Scope my agent evaluation team →
    QUALITY VIEW · WHAT VETTING CHANGES

    Crowd vendor vs. a vetted agentic code evaluation team.

    Where snippet benchmarks and repository-level evaluation differ.

    DIMENSIONGENERIC PROVIDERPITON-GLOBAL-VETTEDWHY IT MATTERS
    TasksToy problemsReal issues in real reposRealistic results
    EnvironmentWorks on my machineReproducible containersComparable runs
    SuccessTests happened to passTests plus code reviewTrue fixes
    ProcessFinal diff onlyFull trajectory reviewedFailure causes found
    SafetyUncheckedRisky commands flaggedSafer agents
    ContaminationPublic benchmarks reusedFresh, private tasksHonest scores
    DATASET FIT

    Who outsources agentic code evaluation, and where agents fail.

    WHERE WE WOULD SAY NO

    When agentic code evaluation belongs with your own team.

    01
    Building your coding agent.
    Your team owns models, prompts and tools.
    02
    Your production codebase.
    Evaluators work only in provided repos and sandboxes.
    03
    Code sample labeling.
    Covered by code annotation.
    QUESTIONS FROM DATA & RESEARCH LEADS

    What coding agent teams ask before they outsource evaluation.

    Straight answers to the questions that decide an agentic code evaluation engagement, from the principals who run them.

    Are evaluators developers?+
    Yes, screened by language and repository experience.
    Can you build private task suites?+
    Yes, from real issues, with hidden tests and reference solutions.
    Do you review full trajectories?+
    Yes, step by step, including commands and reasoning.
    How do you verify fixes?+
    With hidden tests plus code review, so test-gaming fixes count as failures.
    Do you flag unsafe agent actions?+
    Yes, in trajectories and with tasks designed to tempt unsafe behavior.
    Can you evaluate on our private code?+
    Yes, in secure sandboxes with access limited to provided repositories.
    Which languages are covered?+
    Common languages such as Python, JavaScript, TypeScript, Java and Go, by screened skill.
    Is this the same as code annotation?+
    No. Code annotation labels samples; this page evaluates agents on multi-step tasks.
    How are results reported?+
    Pass rates by category, failure distributions and example trajectories.
    What does agentic code evaluation cost?+
    Rates sit within the 2026 bands on this page; pricing depends on tasks, complexity and review depth.
    IN THE AI DATA CLUSTER

    Agentic code evaluation in the AI data stack.

    This page covers evaluating coding agents on multi-step tasks. Code sample labels and RL environments have their own pages.

    THIS PAGE
    Agentic code evaluation

    Repository tasks, trajectory review and verified outcomes.

    CODE LABELS
    Code annotation

    Correctness, quality and security labels on code samples.

    Code annotation →
    RL ENVIRONMENTS
    RL environment development

    Environments, tasks and graders for agent training.

    RL environment development →

    Also serving: agentic code evaluation sits in our AI, Robotics & AVs hub under AI outsourcing. Related pages: code annotation, RL environment development and AI verification. Our article Building a Coding Agent Benchmark From Real Repositories goes deeper on one of the most common questions buyers ask.

    Related specialist pages: multimodal AI evaluation.
    FOR CODING AGENT TEAMS

    Test agents on real code.

    Tell us your agent, languages and task targets. John will bring a shortlist of vetted Philippine providers already evaluating coding agents, free for service buyers.

    WHAT YOU RECEIVE
    ✓A vendor-neutral shortlist of 6–10 Philippine providers already evaluating coding agents.
    ✓Delivered in 48–72 hours, matched to your agent, languages and task targets.
    ✓A security & compliance pre-screen — SOC 2 Type II · ISO 27001 · Sandboxed execution environments.
    TELL US YOUR PRIMARY NEED
    Task suite authoringEnvironment reproductionTrajectory and diff reviewFailure analysis and reportingFull stack
    No fee for buyers · vendor-neutral · we reply within 24 hours
    Authorship, Review & Benchmark Verification
    Authored by:
    Ralf Ellspermann, Founder and CSO of PITON-Global
    Ralf Ellspermann
    Chief Strategy Officer of PITON-Global
    Two Decades Building and Advising Award-Winning Philippine BPO Operations

    Ralf grades Philippine providers on operating data, compliance evidence and leadership depth before any benchmark reaches this page.

    View full bio  →
    Verified by:
    John Maczynski, CEO of PITON-Global
    John Maczynski
    CEO of PITON-Global
    Former Global EVP of the World’s Largest Contact Center · Four Decades of Outsourcing Experience

    John reviews the pricing and contract architecture behind each program, keeping this page grounded in live vendor terms.

    View full bio  →
    Last Reviewed & Verified · October 26, 2026

    Re-audited as rates, regulation and vendor capacity change. Every benchmark on this page is held to PITON-Global’s internal vetting standard.