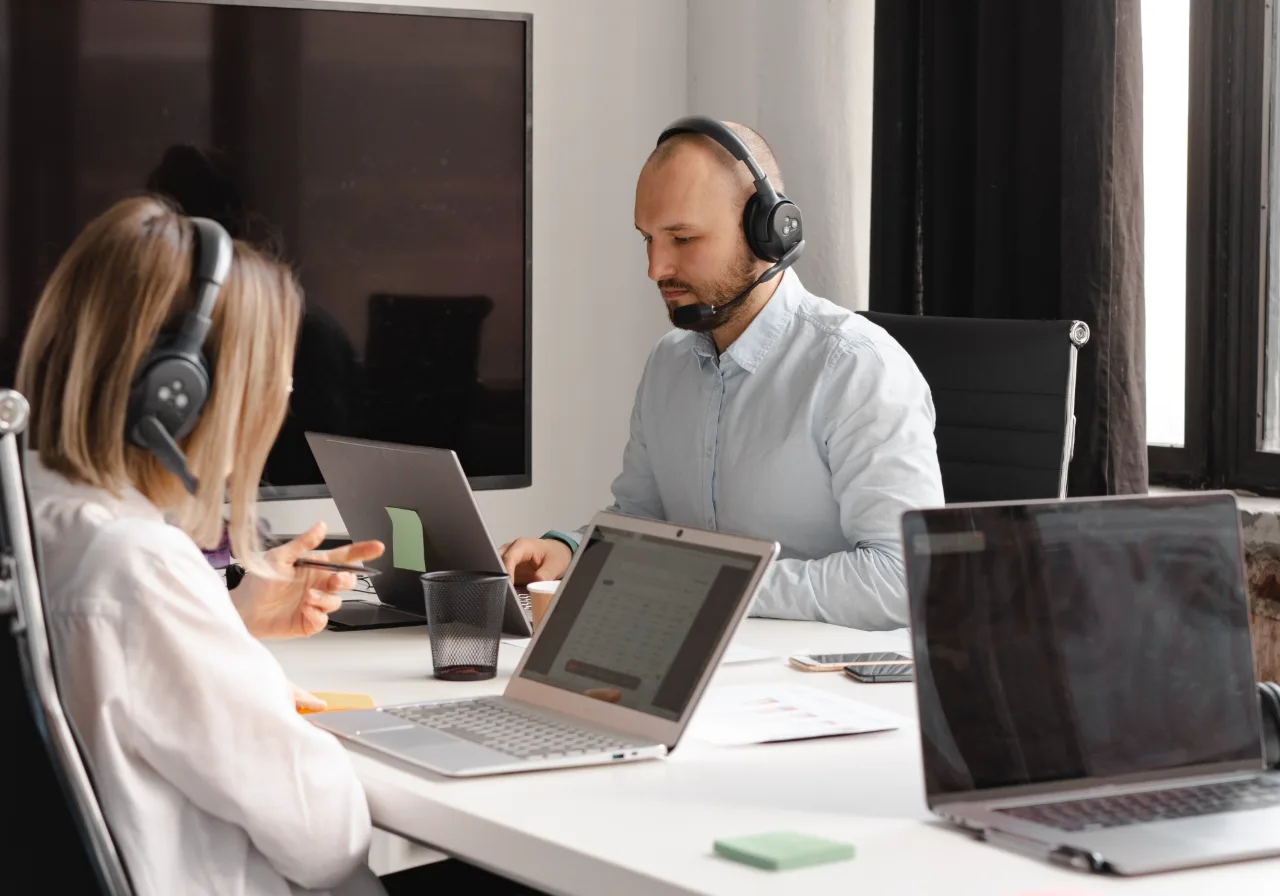
Two specialists with headsets rating model responses at their laptops for a reward model

Reward Modeling Outsourcing Philippines

Models chase the reward, even when it rewards the wrong thing.

The human judgment inside your reward model: rubrics written, comparisons rated, reasoning steps graded and every reward checked for the shortcuts models learn to exploit.

Rubrics + graded comparisons Step-level process labels Validation sets + hacking audits
PITON-GLOBAL SOURCING · 2026 Q4 2026
Vetted provider shortlist
6–10 providers
Shortlist delivered in
48–72 hrs
Advisory fee to buyers
$0
John Maczynski, CEO of PITON-Global, smiling in a navy suit and plaid tie Ralf Ellspermann, Founder and CSO of PITON-Global John Maczynski, CEO · Ralf Ellspermann, CSO
Designed for programs scaling from 5 – 500+ FTEs
FOR BUYERS INUnited States · Canada · United Kingdom · Australiadelivery vetted in the Philippines
A reward model is a compressed copy of human judgment. If the judgment is sloppy, the policy learns the sloppiness.
PLATFORMS & FRAMEWORKS
Pairwise rating toolsRubric scoring platformsStep-level labelingPython and notebooksSpreadsheet analysisSecure environmentsISO 27001SOC 2 Type II
JUDGMENT YOU CAN TRAIN ON

What work does reward modeling outsourcing involve?

The human data and checks behind reward models and automated graders. Specialists write and test rubrics, rate pairwise and graded comparisons, label reasoning steps as correct or flawed, build held-out validation sets, measure agreement and audit trained reward models for reward hacking, length bias and other shortcuts. Your research team owns model architecture and training. General preference collection and model evaluation are on model evaluation and RLHF, and safety testing on AI safety testing.

REWARD MODELS · 2026

Reward models and LLM graders now score most training rollouts. Their quality depends on the human labels used to train and validate them, and on catching the ways policies learn to game them.
A reward model is only as good as the preferences it learned.

Preference ranking, rubric scoring, rationale writing and calibration — expert raters trained on your guidelines.

2026 rates by role ↓
FOR AI RESEARCH & ALIGNMENT LEADS
Your reward model inherits every rater’s blind spot. Pick raters who argue about the right things.

Tell us your domains, reward formats and volumes. We come back with 6–10 vetted providers already supplying expert raters — references checked — free, within 48–72 hours.

VETTED PROVIDERS HOLDSOC 2 Type II · ISO 27001 · Secure, isolated work environments
John Maczynski, CEO of PITON-Global
John Maczynski
CEO · he takes the call himself
+1 402-598-8740

    Free, no obligation. Your details go to John — nobody else.
    TASK TYPES

    The four task families a reward modeling team covers.

    Most teams start with rubric design and pairwise comparisons in one domain, then add process labels and audits.

    Rubric design and testing

    Draft rubrics for each skill, test them on real outputs, measure agreement and refine until raters apply them consistently.

    Pairwise and graded comparisons

    Rate which response is better, by how much and why, with reasons that can be audited.

    Process reward labels

    Label each reasoning step as correct, flawed or unnecessary, so reward models learn to value good reasoning.

    Validation sets and reward audits

    Build held-out sets, measure reward model agreement with humans and probe for length, style and format shortcuts.

    Smiling evaluator at her monitor ranking two model answers for a reward model
    REWARD MODELINGPreference data your reward model can trust.
    GOING DEEPER

    Reward modeling outsourcing in the Philippines

    Reward modeling outsourcing gives post-training teams the human judgment their reward models are built from. A reward model, or an LLM used as a grader, scores outputs so a policy can learn from them at scale. It can only be as good as the comparisons, rubrics and step labels used to train and validate it. When that data is inconsistent or shallow, policies learn to please the grader instead of doing the task well.

    Philippine providers already supply screened raters and domain experts to AI labs, with strong English, analytical backgrounds and experience in rubric-based work. Teams in Manila, Cebu and Clark run rating programs in secure environments with calibration, agreement tracking and expert review.

    WHAT REWARD DATA TEACHES
    Which answer is betterHow much betterWhyWhich steps are soundWhere shortcuts hideHow reliable the reward is
    Reward the behavior you actually want.

    Rubric design and piloting

    Rubrics turn vague goals such as helpfulness, correctness or clarity into criteria raters can apply the same way. Good rubrics define each criterion, give examples at each score level, explain how to weigh criteria against each other and say what to do with edge cases. They are piloted on real model outputs, agreement is measured and wording is revised until disagreement comes from genuine ambiguity rather than unclear instructions.

    Rubrics for LLM graders follow the same process, with human-labeled sets used to check that the grader applies the rubric correctly. See model evaluation for broader evaluation design.

    DEFINED IN EVERY RUBRIC
    CriteriaScore anchorsExamplesWeighting rulesEdge cases
    02 / 07

    Pairwise and graded comparisons

    Most reward models learn from comparisons: two or more responses to the same prompt, ranked or scored by a rater. Raters judge which is better, by how much and on which criteria, and write short reasons. Ties and “both bad” options are allowed, because forcing a preference adds noise. Prompts are sampled to cover the skills and difficulty levels the policy must learn.

    Reasons make labels auditable and help researchers understand what the reward model is learning. See LLM training and fine-tuning for the supervised data that often precedes preference training.

    RECORDED ON EVERY COMPARISON
    Preferred responseMarginCriteria appliedReasonTies and both-bad

    Process reward labels for reasoning

    For math, code, science and multi-step reasoning, the final answer is not enough. Process reward models score each step, which helps policies learn sound reasoning rather than lucky guesses. Specialists read solutions step by step and label each one as correct, incorrect, unnecessary or unclear, and mark the first error. This work needs domain experts and careful definitions.

    Step labels also help find where models typically go wrong. See code annotation for step-level review of code and agentic code evaluation for multi-step coding tasks.

    LABELED ON EVERY STEP
    CorrectIncorrectUnnecessaryUnclearFirst error
    04 / 07

    Validation sets and reward accuracy

    Training loss says little about whether a reward model agrees with people. Held-out validation sets, labeled by calibrated raters and kept separate from training data, measure how often the reward model ranks responses the way humans do, by domain and difficulty. Sets are versioned so results stay comparable across reward model versions.

    Validation results tell researchers where more data is needed and whether a new reward model is safe to use. See AI verification for human review in production.

    MEASURED ON VALIDATION SETS
    Human agreementAccuracy by domainAccuracy by difficultyCalibrationVersion comparison

    Reward hacking and bias audits

    Policies optimize hard against reward models and find their weaknesses: longer answers, confident tone, flattering language, specific formatting or keywords that score well without improving quality. Audits probe reward models with controlled variations, such as the same answer made longer or more confident, and compare reward scores with human judgments. Findings guide new data and rubric changes.

    Sycophancy and false confidence are also checked, because they make models less trustworthy. See AI safety testing for adversarial testing.

    PROBED IN EVERY AUDIT
    Length biasConfidence biasFormatting biasSycophancyKeyword gaming
    06 / 07

    Domain experts and rater quality

    Judging advanced math, code, medicine, law or finance needs people who know the field. Programs screen experts with domain tests, assign them by skill and track their agreement with gold labels and each other. Raters who drift are recalibrated or reassigned. Expert time is expensive, so programs route easy comparisons to general raters and hard ones to experts.

    See our talent and training guide for screening and medical data annotation for clinical expertise.

    TRACKED PER RATER
    Domain test scoreGold agreementPeer agreementDriftAssignment level

    Choosing a reward modeling partner

    When you compare vendors, ask about rubric design experience, domain expert depth, process labeling methods, agreement statistics, audit capability and how they keep raters from seeing which model produced which response. Ask for a pilot that includes a small reward audit.

    Vetted mid-sized Philippine providers usually start reward programs with 10 to 50 raters and report comparisons per day, agreement scores, expert share, validation accuracy and audit findings. See the AI, robotics and AVs hub.

    ASK EVERY VENDOR FOR
    Rubric experienceExpert depthProcess labelingAgreement statisticsAudit capability
    REWARD MODELING · WHO COMMISSIONS THE DATA

    Who commissions reward modeling.

    Teams training reward models, process reward models or LLM graders who need expert human judgment, well-tested rubrics and independent checks on reward quality.

    ✓Foundation model labs
    ✓Reasoning and math model teams
    ✓Code model developers
    ✓Enterprise AI platform teams
    ✓Agent developers
    ✓Research labs
    REWARD MODELING · PIPELINE

    Pipeline and QA

    Your researchers define skills, reward formats and acceptance criteria. The vendor drafts and pilots rubrics, calibrates raters, labels at volume and audits trained reward models against held-out human judgments.

    STEP 1DesignRubrics drafted and piloted on real outputs.
    STEP 2CalibrateRaters aligned on gold comparisons.
    STEP 3LabelComparisons and step labels at volume.
    STEP 4AuditReward model checked for shortcuts.
    WHERE DATA QUALITY SLIPS

    Two ways outsourced reward modeling loses quality.

    Both are fixable before go-live.

    FRICTION POINT 01 · THE LONGER-IS-BETTER REWARD
    Reward models that prefer verbose answers
    Policies learn padding instead of quality.
    AUDIT BEFORE SIGNING: Ask how the vendor measures and controls length bias in labels and audits.
    FRICTION POINT 02 · THE CONFIDENT WRONG STEP
    Final answers that are right for the wrong reasons
    Outcome-only rewards teach lucky reasoning.
    AUDIT BEFORE SIGNING: Ask how step-level labels are defined and checked.
    REWARD MODELING · QUALITY RUBRIC

    What a preference judgment is scored on

    Rubrics break a preference into parts so raters agree for the same reasons.

    DimensionWhat raters checkTypical failure
    CorrectnessFacts and reasoning hold upPreferring the confident wrong answer
    Instruction followingThe response does what was askedRewarding extra content nobody asked for
    ProcessEach reasoning step is validRight answer reached by a broken step
    Safety and policyThe response stays within policyRewarding refusals that weren’t needed
    Style and lengthLength and tone fit the requestPreferring the longer response by default
    PRICING TOPOGRAPHY · 2026 RATE CARD

    Rates by annotator and reviewer role, 2026

    CORE ROLERATE (USD/HR)OPERATIONAL PROFILETIER
    Preference rater$8–$12Pairwise and graded comparisons.R
    Domain expert rater$14–$18Math, code, science, legal and medical judgments.R
    Process label specialist$12–$16Step-level correctness labels.R
    QA reviewer$14–$16Gold sets, agreement and calibration.R
    Team lead$14–$18Rubrics, audits and reporting.R

    Ask each vendor to price against comparisons per week, domain mix, step-label share and audit depth. Rates confirmed per engagement.

    Scope my reward modeling team →
    QUALITY VIEW · WHAT VETTING CHANGES

    Crowd vendor vs. a vetted reward modeling team.

    Where ad hoc preference labels and a managed reward program differ.

    DIMENSIONGENERIC PROVIDERPITON-GLOBAL-VETTEDWHY IT MATTERS
    RubricsOne-line instructionsTested rubrics with examplesConsistent judgments
    RatersWhoever is availableScreened by domainExpert-level labels
    GranularityFinal answer onlyStep-level process labelsRewards for good reasoning
    ValidationTraining lossHeld-out human agreementKnown reward accuracy
    ShortcutsFound after trainingAudited for length and style biasFewer hacked rewards
    ReportingVolume deliveredAgreement and audit findingsEvidence for research
    DATASET FIT

    Who outsources reward modeling work, and where reward models fail.

    WHERE WE WOULD SAY NO

    When reward modeling belongs with your own team.

    01
    Training the reward model.
    Your researchers own architecture, training and deployment.
    02
    Red-teaming and safety policy.
    Covered by AI safety testing.
    03
    Production output review.
    Covered by AI verification.
    QUESTIONS FROM DATA & RESEARCH LEADS

    What post-training teams ask before they outsource reward modeling.

    Straight answers to the questions that decide a reward modeling engagement, from the principals who run them.

    How is this different from RLHF services?+
    This page focuses on reward model data and audits; broader RLHF programs are on the model evaluation and RLHF page.
    Can you design rubrics for us?+
    Yes. Rubrics are drafted, piloted on real outputs and refined until agreement is stable.
    Do you label reasoning steps?+
    Yes. Domain experts label each step and mark the first error.
    Can you test our reward model for bias?+
    Yes. Audits probe length, confidence, formatting and sycophancy against human judgments.
    Who are the raters?+
    Screened general raters plus domain experts assigned by skill.
    How is agreement measured?+
    Against gold labels and between raters, reported by domain and difficulty.
    Can you validate an LLM grader?+
    Yes, with human-labeled sets that check whether it applies the rubric correctly.
    Do raters know which model wrote each response?+
    No. Comparisons are blind.
    Is the work done securely?+
    Yes, in secure environments with access controls and no downloads.
    What does reward modeling cost?+
    Rates sit within the 2026 bands on this page; pricing depends on domains, volume and audit depth.
    IN THE AI DATA CLUSTER

    Reward modeling in the AI data stack.

    This page covers human data and audits for reward models. General preference work and safety testing have their own pages.

    THIS PAGE
    Reward modeling

    Rubrics, comparisons, process labels and reward audits.

    RLHF
    Model evaluation and RLHF

    Preference collection, evaluation and RLHF programs.

    Model evaluation and RLHF →
    SAFETY
    AI safety testing

    Red-teaming, jailbreak and harm evaluation.

    AI safety testing →

    Also serving: reward modeling sits in our AI, Robotics & AVs hub under AI outsourcing. Related pages: model evaluation and RLHF, LLM training and fine-tuning and code annotation. If you are scoping this work, start with Reward Hacking: How to Detect It Before Your Policy Learns It.

    Related specialist pages: multimodal AI evaluation and RL environment development.
    FOR POST-TRAINING & REWARD MODEL TEAMS

    Reward what you actually want.

    Tell us your domains, reward formats and volumes. John will bring a shortlist of vetted Philippine providers already supplying expert raters, free for service buyers.

    WHAT YOU RECEIVE
    ✓A vendor-neutral shortlist of 6–10 Philippine providers already supplying expert raters.
    ✓Delivered in 48–72 hours, matched to your domains, reward formats and volumes.
    ✓A security & compliance pre-screen — SOC 2 Type II · ISO 27001 · Secure, isolated work environments.
    TELL US YOUR PRIMARY NEED
    Rubric design and testingPairwise and graded comparisonsProcess reward labelsValidation sets and reward auditsFull stack
    No fee for buyers · vendor-neutral · we reply within 24 hours
    Authorship, Review & Benchmark Verification
    Authored by:
    Ralf Ellspermann, Founder and CSO of PITON-Global
    Ralf Ellspermann
    Chief Strategy Officer of PITON-Global
    Two Decades Building and Advising Award-Winning Philippine BPO Operations

    Ralf grades Philippine providers on operating data, compliance evidence and leadership depth before any benchmark reaches this page.

    View full bio  →
    Verified by:
    John Maczynski, CEO of PITON-Global
    John Maczynski
    CEO of PITON-Global
    Former Global EVP of the World’s Largest Contact Center · Four Decades of Outsourcing Experience

    John reviews the pricing and contract architecture behind each program, keeping this page grounded in live vendor terms.

    View full bio  →
    Last Reviewed & Verified · October 26, 2026

    Re-audited as rates, regulation and vendor capacity change. Every benchmark on this page is held to PITON-Global’s internal vetting standard.