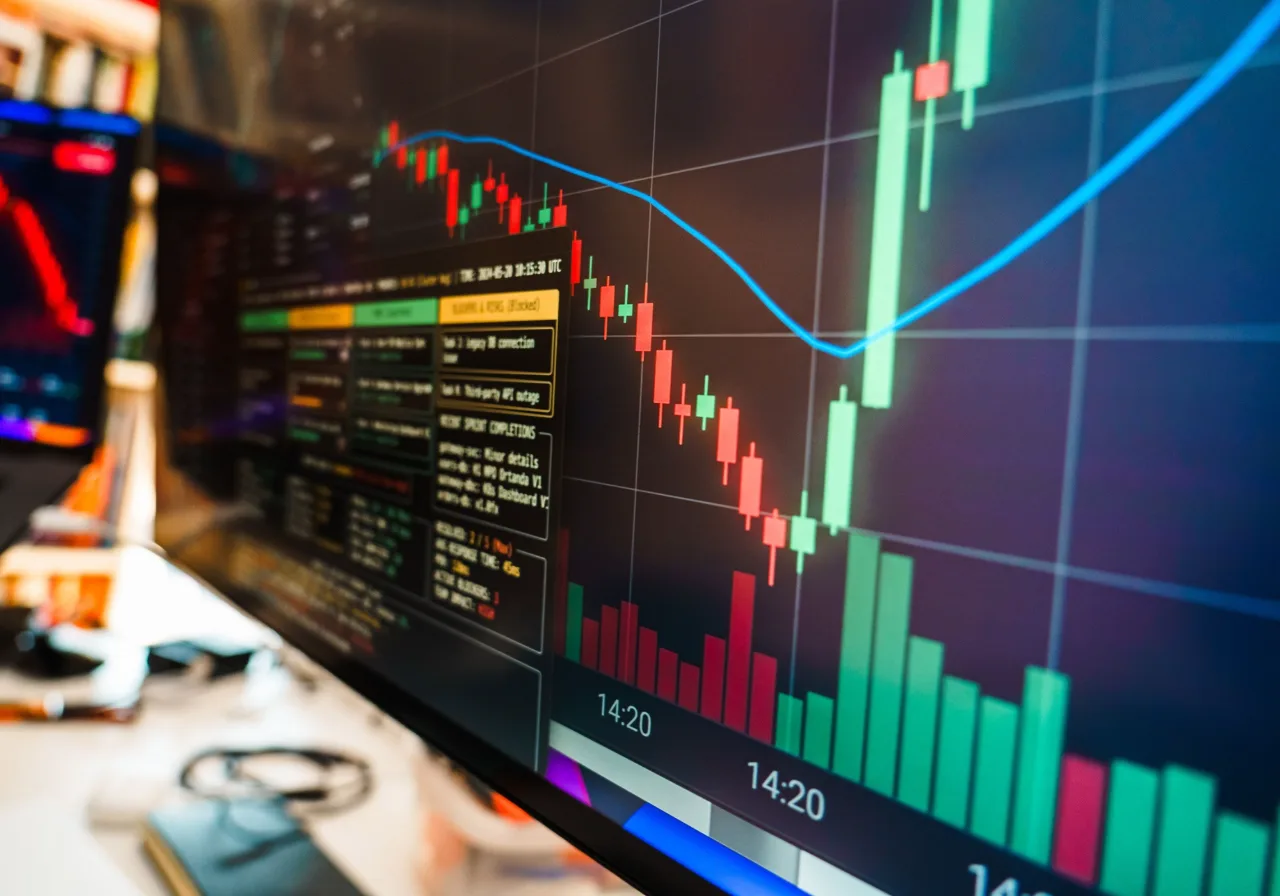
Monitor showing a chart and rating task panel, the human judgments that train a recommender

Recommendation Data Labeling Outsourcing Philippines

Recommenders learn taste from human judgment, not just clicks.

Human judgments that teach recommenders taste: which items belong together, which suggestions make sense for a user and which feeds feel fresh, fair and safe.

Recommendation relevance judgments Item attributes + similarity pairs Feed quality + diversity review
PITON-GLOBAL SOURCING · 2026 Q4 2026
Vetted provider shortlist
6–10 providers
Shortlist delivered in
48–72 hrs
Advisory fee to buyers
$0
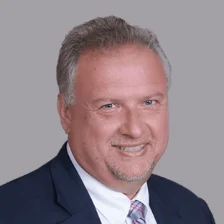
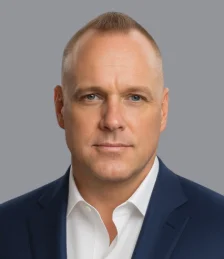
John Maczynski, CEO of PITON-Global, smiling in a navy suit and plaid tie Ralf Ellspermann, Founder and CSO of PITON-Global John Maczynski, CEO · Ralf Ellspermann, CSO
Designed for programs scaling from 5 – 500+ FTEs
FOR BUYERS INUnited States · Canada · United Kingdom · Australiadelivery vetted in the Philippines
Click data tells a recommender what people did. Human labels tell it what they would have wanted.
PLATFORMS & FRAMEWORKS
Labeling platformsSide-by-side rating toolsProduct catalogsContent taxonomiesRubric scoringSecure environmentsISO 27001SOC 2 Type II
TEACHING RECOMMENDERS TASTE

What work does recommendation data labeling outsourcing involve?

Human labels that train and evaluate recommender systems. Raters judge whether recommendations fit a user context, label item attributes and taxonomies, mark similar, substitute and complementary item pairs, review feeds for quality, diversity and policy issues and build evaluation sets, following rubrics with agreement checks. Your ML team owns models and metrics. Catalog content operations are on marketplace catalog management, and general labeling on data labeling.

RECOMMENDERS · 2026

Recommenders drive what people buy, watch and read. Engagement data alone rewards clickbait and repetition; human judgments add relevance, quality and diversity.
Recommendations improve when people judge what is actually relevant.

Relevance rating, query and item labeling, side-by-side ranking and taxonomy tagging — raters trained on your guidelines.

2026 rates by role ↓
FOR SEARCH & RECOMMENDATION LEADS
Relevance is a judgment call, made thousands of times a day. Get raters who make it consistently.

Tell us your platform, tasks and locales. We come back with 6–10 vetted providers already rating relevance and quality — references checked — free, within 48–72 hours.

VETTED PROVIDERS HOLDSOC 2 Type II · ISO 27001 · Secure, isolated work environments
John Maczynski, CEO of PITON-Global
John Maczynski
CEO · he takes the call himself
+1 402-598-8740

    Free, no obligation. Your details go to John — nobody else.
    RECOMMENDATION LABELING · HAND-OFF FLOW

    How recommendation judgments are produced

    Ratings only help if raters see what the user saw. Each batch moves through the same steps.

    01 →
    User context
    Raters see the session, query or profile behind the recommendation.
    02 →
    Judgment
    Relevance, similarity or feed quality rated against the rubric.
    03 →
    Calibration
    Disagreements reviewed and the rubric tightened.
    04 →
    Locale check
    Results checked for cultural and market fit.
    05 ■
    Delivery
    Judgments delivered for training or offline evaluation.
    TASK TYPES

    The four task families a recommendation labeling team covers.

    Most teams start with offline relevance evaluation of model changes, then add attributes, similarity pairs and feed audits.

    Recommendation relevance judgments

    Judge whether recommended items fit a user profile, history or context, on graded scales with reasons.

    Item attributes and taxonomy

    Label style, genre, audience, use case and other attributes that help new items find the right users.

    Similarity and complementarity pairs

    Mark items that are substitutes, complements or unrelated, for bundles, alternatives and “goes with” modules.

    Feed quality and diversity review

    Review feeds for repetition, staleness, low quality, policy issues and fairness to creators and sellers.

    Shopper paying at a tablet checkout, the kind of purchase signal recommendation labelers judge
    RECOMMENDATION DATA LABELINGRelevance judged by people, not proxies.
    GOING DEEPER

    Recommendation data labeling outsourcing in the Philippines

    Recommendation data labeling outsourcing gives personalization teams human judgment at scale. Recommenders learn mostly from behavior: clicks, views, purchases and skips. Behavior is abundant but noisy; it rewards what grabs attention, not always what people value, and it says little about new items. Human raters add the missing signal: whether a recommendation makes sense, which items belong together and whether a feed feels fresh and trustworthy.

    Philippine raters are experienced with US, UK and Australian consumer culture, brands and media, which makes their judgments relevant for English-language platforms. Providers in Manila, Cebu and Davao run rating programs with locale specialists for other markets.

    WHAT HUMAN LABELS ADD
    RelevanceItem understandingSimilarityDiversityQualityOffline evaluation
    Judge what users would want, not just what they clicked.
    01 / 07

    Rubrics and user context

    Good recommendation judgments start with clear user context: a profile, recent history, a stated goal or a scenario such as “shopping for a gift” or “wants something new.” Rubrics define graded relevance levels, what counts as a good alternative, when repetition is a problem and how to treat sensitive items. Raters explain their judgments briefly, which helps calibration.

    Calibration sessions align raters on borderline cases, and agreement is tracked per task. See model evaluation for rubric design and side-by-side methods.

    DEFINED IN EVERY RUBRIC
    User contextRelevance levelsGood alternativesRepetition rulesSensitive items

    Item attributes and cold start

    New items have no behavior data, so recommenders rely on attributes to place them. Annotators label style, genre, mood, audience, occasion, material, use case and other attributes that matter in each domain, using a consistent taxonomy. For media, labels may include themes, tone and content advisories.

    Attribute quality decides how fast new items reach the right users. See marketplace catalog management for catalog attribute operations.

    LABELED FOR NEW ITEMS
    Style and genreAudienceOccasion and useMood and toneContent advisories
    03 / 07

    Similarity, substitutes and complements

    Many recommendation modules depend on item relationships: “similar items,” “customers also bought,” bundles and outfit or recipe suggestions. Annotators label pairs as substitutes, complements, unrelated or poor matches, with reasons. These labels train and evaluate relationship models and catch embarrassing pairings before customers see them.

    See e-commerce outsourcing and retail outsourcing for merchandising operations that use these modules.

    LABELED ON ITEM PAIRS
    SubstituteComplementUnrelatedPoor matchReason

    Feed quality, diversity and fairness

    Feeds can become repetitive, stale or dominated by a few creators or sellers. Reviewers audit sample feeds for repetition, novelty, quality, clickbait, policy issues and fairness to new or smaller creators. Findings guide ranking changes and diversity rules. Policy issues are routed to trust and safety teams.

    See trust and safety and content moderation for policy enforcement, and social media for content operations.

    AUDITED IN EVERY FEED SAMPLE
    RepetitionNoveltyQualityClickbaitCreator fairness
    05 / 07

    Offline evaluation of model changes

    Before A/B tests, teams compare model versions offline. Raters judge recommendations from two models side by side for the same users and contexts, without knowing which model produced which list. Results show where a new model is better or worse, so only promising changes reach live tests.

    Evaluation sets are versioned and reused, so results stay comparable over time. See AI verification for review of AI outputs in production.

    MEASURED IN EVERY COMPARISON
    Side-by-side listsBlind ratingWin rateFailure examplesVersioned sets

    Locales and cultural relevance

    What counts as relevant varies by market: holidays, sizes, brands, humor, music and food. Locale specialist raters judge recommendations for their own markets, so global platforms do not apply one culture’s taste everywhere. Language tiers follow the multilingual rate band.

    See multilingual support for language coverage and visual search support for image-based discovery.

    COVERED BY LOCALE
    Local holidaysLocal brandsSizes and unitsHumor and toneLanguage
    07 / 07

    Choosing a recommendation labeling partner

    When you compare vendors, ask about consumer domain experience, rubric design, calibration methods, agreement scores, locale coverage and how they keep raters unbiased in side-by-side tests. Ask for a pilot evaluation of a real model change.

    Vetted mid-sized Philippine providers usually start recommendation programs with 10 to 60 raters and report judgments per day, agreement scores, model win rates, rework and locale coverage. See the retail and e-commerce hub for related programs.

    ASK EVERY VENDOR FOR
    Domain experienceRubric designCalibrationAgreement scoresLocale coverage
    RECOMMENDATION DATA LABELING · WHO COMMISSIONS THE DATA

    Who commissions recommendation data labeling.

    Teams building recommender systems who need human judgments to complement behavioral data, evaluate new models and audit feed quality.

    ✓E-commerce platforms
    ✓Marketplaces
    ✓Streaming services
    ✓Social and content apps
    ✓Travel and booking platforms
    ✓Retail media networks
    RECOMMENDATION DATA LABELING · PIPELINE

    Pipeline and QA

    Your team defines tasks, rubrics and metrics. The vendor screens and calibrates raters, judges recommendations at volume and reports agreement and model comparisons.

    STEP 1DefineTasks, rubrics and user contexts set.
    STEP 2CalibrateRaters scored on gold examples.
    STEP 3RateJudgments collected at volume.
    STEP 4ReportAgreement and model comparisons delivered.
    WHERE DATA QUALITY SLIPS

    Two ways outsourced recommendation data labeling loses quality.

    Both are fixable before go-live.

    FRICTION POINT 01 · THE ECHO CHAMBER
    Feeds that show more of the same
    Engagement-only models narrow what users see and drive fatigue.
    AUDIT BEFORE SIGNING: Ask how raters judge diversity and novelty, not just relevance.
    FRICTION POINT 02 · THE UNCLEAR USER
    Raters guessing what a user wants
    Without clear context, judgments become personal taste.
    AUDIT BEFORE SIGNING: Ask how user contexts are presented and how agreement is measured.
    PRICING TOPOGRAPHY · 2026 RATE CARD

    Rates by annotator and reviewer role, 2026

    CORE ROLERATE (USD/HR)OPERATIONAL PROFILETIER
    Recommendation rater$6–$10Relevance and fit judgments.R
    Attribute annotator$6–$10Item attributes and taxonomy labels.R
    Locale specialist rater$12–$18Market and language-specific judgments.R
    QA reviewer$14–$16Gold sets, sampling and calibration.R
    Team lead$14–$18Rubrics, calibration and reporting.R

    Ask each vendor to price against judgments per week, task complexity, locales and overlap for agreement. Rates confirmed per engagement.

    Scope my recommendation labeling team →
    QUALITY VIEW · WHAT VETTING CHANGES

    Crowd vendor vs. a vetted recommendation labeling team.

    Where engagement data alone and human-labeled programs differ.

    DIMENSIONGENERIC PROVIDERPITON-GLOBAL-VETTEDWHY IT MATTERS
    RelevanceInferred from clicksJudged against user contextFewer bad suggestions
    Cold startNo data for new itemsAttributes and similarity labeledNew items surface faster
    DiversitySame items repeatedDiversity and novelty reviewedFresher feeds
    QualityClickbait rewardedQuality and policy checksHealthier engagement
    LocalesOne marketLocale specialist ratersLocal relevance
    EvaluationA/B tests onlyOffline human evaluation setsFaster iteration
    DATASET FIT

    Who outsources recommendation labeling, and where it falls short.

    WHERE WE WOULD SAY NO

    When recommendation data labeling belongs with your own team.

    01
    Model design and ranking metrics.
    Your ML team owns models and metrics.
    02
    Search results rating.
    Search result relevance is outside this page’s scope.
    03
    Content policy decisions.
    Policy enforcement follows your trust and safety teams.
    QUESTIONS FROM DATA & RESEARCH LEADS

    What personalization teams ask before they outsource recommendation labeling.

    Straight answers to the questions that decide a recommendation data labeling engagement, from the principals who run them.

    Does this replace click data?+
    No. Human judgments complement behavior data with relevance, quality and diversity signals.
    Can raters evaluate model changes offline?+
    Yes, with blind side-by-side comparisons on the same user contexts.
    Do they label item attributes?+
    Yes, using your taxonomy, to help new items reach the right users.
    Can they label substitutes and complements?+
    Yes, with reasons, for similar-item and bundle modules.
    Do they audit feeds?+
    Yes, for repetition, novelty, quality, clickbait and creator fairness.
    Is this search relevance rating?+
    No. Search results rating is outside this page; this covers recommendations and feeds.
    Can they rate for other markets?+
    Yes, through locale specialist raters.
    How is rater bias controlled?+
    With blind tests, calibration and agreement tracking.
    How is quality measured?+
    With agreement scores, gold-set accuracy and model win rates.
    What does recommendation labeling cost?+
    Rates sit within the 2026 bands on this page; pricing depends on volume, complexity and locales.
    IN THE AI DATA CLUSTER

    Recommendation labeling in the AI data stack.

    This page covers human judgments for recommenders. Catalog operations and general labeling have their own pages.

    THIS PAGE
    Recommendation data labeling

    Relevance, attributes, similarity and feed quality labels.

    CATALOG
    Marketplace catalog management

    Listings, attributes and catalog health.

    Marketplace catalog management →
    GENERAL LABELING
    Data labeling

    Image, video and text annotation across tasks.

    Data labeling →

    Also serving: recommendation data labeling sits in our AI, Robotics & AVs hub under AI outsourcing. Related pages: marketplace catalog management, model evaluation and e-commerce outsourcing. Related reading: Offline Recommender Evaluation With Human Raters: When Clicks Are Not Enough.

    Related specialist pages: sensor and LiDAR data collection, financial data annotation and egocentric data collection.
    FOR PERSONALIZATION & ML TEAMS

    Add human taste to your recommender.

    Tell us your platform, tasks and locales. John will bring a shortlist of vetted Philippine providers already rating relevance and quality, free for service buyers.

    WHAT YOU RECEIVE
    ✓A vendor-neutral shortlist of 6–10 Philippine providers already rating relevance and quality.
    ✓Delivered in 48–72 hours, matched to your platform, tasks and locales.
    ✓A security & compliance pre-screen — SOC 2 Type II · ISO 27001 · Secure, isolated work environments.
    TELL US YOUR PRIMARY NEED
    Recommendation relevance judgmentsItem attributes and taxonomySimilarity and complementarity pairsFeed quality and diversity reviewFull stack
    No fee for buyers · vendor-neutral · we reply within 24 hours
    Authorship, Review & Benchmark Verification
    Authored by:
    Ralf Ellspermann, Founder and CSO of PITON-Global
    Ralf Ellspermann
    Chief Strategy Officer of PITON-Global
    Two Decades Building and Advising Award-Winning Philippine BPO Operations

    Ralf grades Philippine providers on operating data, compliance evidence and leadership depth before any benchmark reaches this page.

    View full bio  →
    Verified by:
    John Maczynski, CEO of PITON-Global
    John Maczynski
    CEO of PITON-Global
    Former Global EVP of the World’s Largest Contact Center · Four Decades of Outsourcing Experience

    John reviews the pricing and contract architecture behind each program, keeping this page grounded in live vendor terms.

    View full bio  →
    Last Reviewed & Verified · October 26, 2026

    Re-audited as rates, regulation and vendor capacity change. Every benchmark on this page is held to PITON-Global’s internal vetting standard.